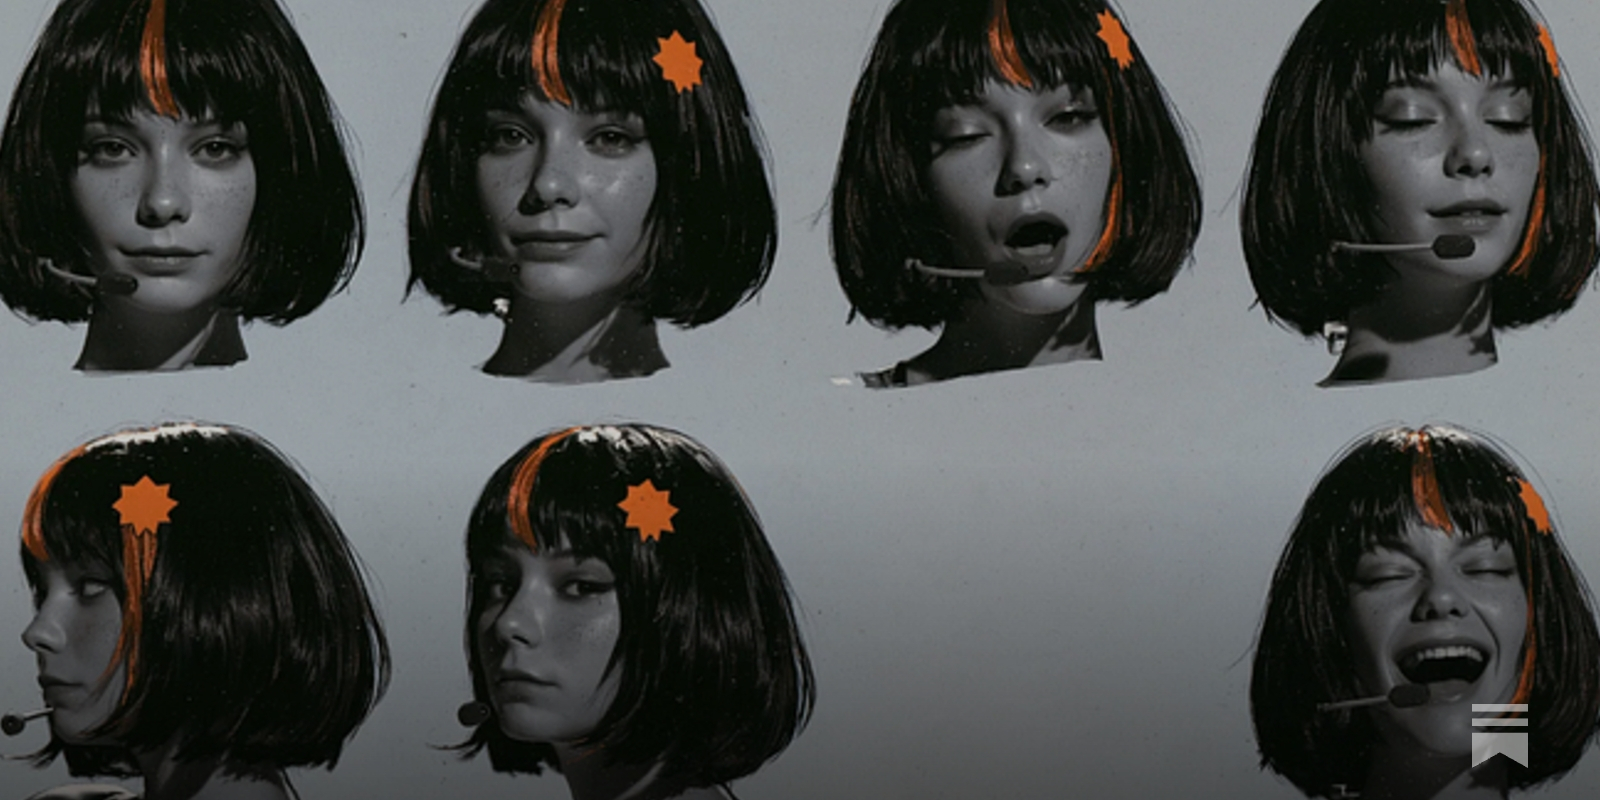
Asterisk Magazine published an interview with RJ Tevonian (@anabology), the creator of 'slopcore' music videos featuring the AI character Claudia. The main takeaway from the article: in AI video, the center of gravity is shifting from image generation to model orchestration — Claude Opus 5.5 works as a dispatcher for a multi-model pipeline, where Suno creates the music, Midjourney assembles the character, Seedance draws the frames, and MiniMax H3 handles lip-sync. Individual techniques from this pipeline can be tried today: everything works through public APIs and does not require proprietary GPUs.
What Happened
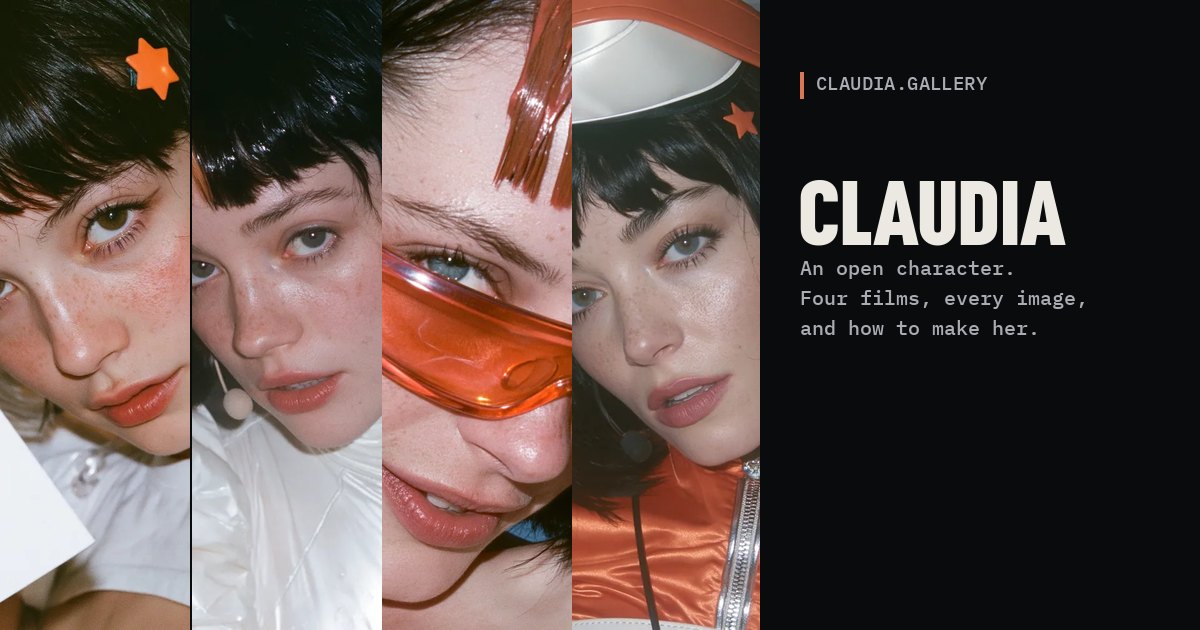
Asterisk Magazine released the piece *Behind the scenes of those Claude slopcore music videos* — an interview with RJ Tevonian, who publishes clips featuring the AI character Claudia under the handle @anabology. In it, the author breaks down his pipeline step by step. Claude Opus 5.5 works as a dispatcher: it writes song lyrics, generates 30–40 variations of each track via Suno (from which working ones are selected), creates storyboards, and animates scenes using JavaScript directly in the browser. Then the video model Seedance repaints the frames, adding lighting and texture. Character appearance consistency is maintained through external state: character sheets are prepared in Midjourney, pinpoint edits are made via GPT Image 2.5 Sunburst or Ideogram, and precise lip synchronization is performed by the more affordable MiniMax H3 model followed by remastering. The author's finished works are collected in a portfolio at claudia.gallery.
Context
'Slopcore' is a young AI video genre whose aesthetic is consciously built on the imperfection of generations: artifacts are not hidden but preserved in the spirit of wabi-sabi, editing is fast and choppy, and clips are overloaded with dense cultural references. The publication came amid lively discussion of AI video on Hacker News, where readers debate what such works say about the current state of generative models. Technically, the conclusion about role separation is notable: modern video models do not maintain character identity between scenes on their own, so consistency is ensured externally — through separate artifacts and post-processing. The overall picture aligns with a broader trend: 'planning by code' is taken over by the LLM, while the synthesis of audio, images, and video remains with specialized models.
Why This Matters for the Industry
For the industry, this case is a practical demonstration of the 'expensive orchestrator model plus cheap specialized executors' pattern. Claude Opus 5.5 here does not generate pixels; it writes lyrics, prompts, storyboards, and JavaScript animation, coordinating Suno, Midjourney, Seedance, GPT Image 2.5 Sunburst / Ideogram, and MiniMax H3. Routing by price tiers is visible in its pure form: the specific subtask of lip-sync is performed by a cheap model, while high-quality results are achieved through remastering on top of its output. The cost of producing a music video drops from a studio budget to the level of API bills and the time of a single operator, with the entire pipeline running through public APIs without proprietary GPUs. The weak point of the pattern — character consistency — creates demand for character state management tools and long-term identity benchmarks. However, the business model in the case is not shown: the technique is validated, but the market and defensible advantage have not yet been demonstrated.
Why This Matters for Users
For readers who make AI videos themselves, the material stands out by providing working techniques rather than abstract speculations about the future of the genre. The portfolio at claudia.gallery allows viewers to first see the result in full and soberly assess the quality of the work. The techniques are reproducible by hand today: character sheets for character consistency, lip-sync on a cheap model with expensive remastering, and JavaScript animation as a storyboard framework, with JavaScript turning out to be Claude's 'comfort zone' for code. Everything is assembled from public APIs and without GPUs, but this is at the level of prototypes and custom scripts: there is no ready-made SaaS, so the minimum viable product must be pieced together from services independently.
What Is Still Unknown / Limitations
This is a self-reported case from a single author, not a methodology: the interview lacks ablation experiments and metrics, as well as figures on cost, build time, and the percentage of rejected generations, so the reduction in production cost should be considered a hypothesis rather than a measured result. Claims of a 'reproducible recipe' require published prompts, character sheets, and model parameters, which the publication does not fully disclose. The business component also remains unknown: monetization, market, and defensible advantage are not shown in the material. Finally, the transferability of the pattern to other genres and teams has not yet been tested by independent reproduction.
Sources
- Behind the scenes of those Claude slopcore music videos — Asterisk Magazine (interview with RJ Tevonian)
- Behind the scenes of those Claude slopcore music videos | Hacker News (discussion)
- Claudia · claudia.gallery (AI video portfolio, mentioned in HN discussion)
Author
Look at AI, editorial team