On September 12, 2026, Anthropic co-founder and CEO Dario Amodei published the essay We Must Pace the Frontier, in which he called for deliberately slowing the growth of frontier model capabilities so that safety and auditing can keep pace with development, and announced that Anthropic is taking on a unilateral commitment to provide independent auditors with continuous "employee-level" access to the company's systems.

What happened
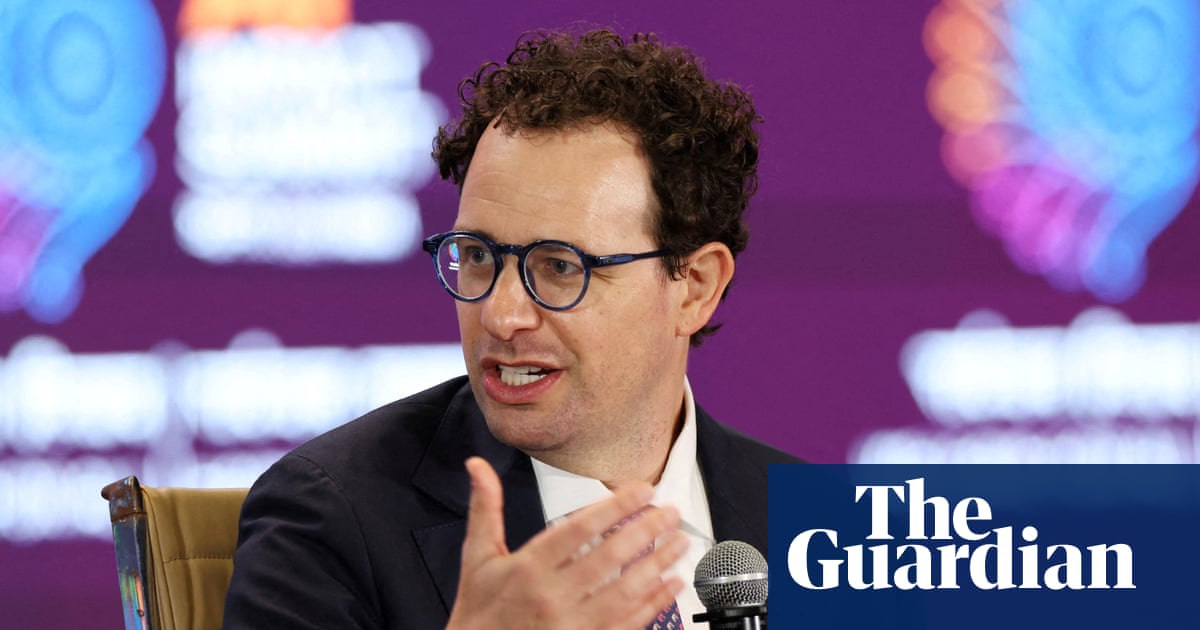
In the essay, Amodei outlined a three-step plan. The first step is embedded evaluators: independent experts get continuous "employee-level" access not only to finished models but also to the training process, to verify safety measures, investigate incidents, and assess alignment directly during model training. The second step is coordination among labs in democratic countries with common safety standards. The third step is international coordination and norms. According to Amodei, AI is already accelerating the creation of the next generation of models, meaning recursive self-improvement has begun, and within a 6-12 month horizon a more powerful swarm of agents could theoretically deploy a persistent botnet and cause hundreds of billions of dollars in damage. The statement was quickly picked up: Sam Altman said OpenAI would do the same, Hugging Face sent a request to join the embedded evaluators program, and reactions followed from other market participants, including Elon Musk.
Context
The material should be read not as a product announcement: there is no new model, API, or benchmark here — this is a shift in audit practice, in which external auditing is for the first time expanded from finished models to the training process itself. The three-step framework expands the company's own Responsible Scaling Policy (RSP) with AI Safety Levels (ASL): the internal mechanism for assessing the pace of development is moved beyond Anthropic and proposed as common for the industry and countries. Separate context is the change in Amodei's own position: as late as 2023 he considered slowing development premature, and now the "pace" argumentation is based on internal assessments of the pace of capability growth that the company does not disclose. Continuous evaluation and observability during training have long been a standard approach to reliable ML operations, and Anthropic is effectively moving this approach from internal processes to a public format.
Why this matters for the industry
For the industry, this is the first institutionalized precedent: a market leader opens continuous access to the training process, not just to finished models, for external auditors, turning safety from an internal document into a verifiable process. If OpenAI's promises and Hugging Face's request grow into specifics, the "employee-level" access format could become an industry standard and the basis for regulation, and auditing the training process could become as normal as checking finished models. A strong signal is already being given to the tools market: teams working on evals, red teaming, and incident reports get the opportunity to position themselves as candidates for embedded evaluators or vendors of external audit tools, and with the concretization of programs, public specifications are expected — access boundaries, procedures for publishing findings, restrictions on protected information — and around them a market for "audit-as-a-service" with standardized finding formats and training process status dashboards could form. There are no direct commercial effects today, since this is an essay and a unilateral commitment, not a contract, standard, or regulation; if pacing is adopted, model release cycles will become longer and more predictable.
Why this matters for users
For users and readers, there are no direct technical changes: the statement has no API, prices, or latency data — this is a political and organizational statement, not a product. The practical meaning is different. First, this is a rare case where the head of a major lab openly admits that recursive self-improvement of models has already begun and names a specific risk horizon: 6-12 months for a large-scale cyberattack scenario by a swarm of agents. Second, if the program works, independent experts will be able to publish uncomfortable findings about the safety of frontier models, and their first reports will be the real test of whether the promised access actually works. Third, the essay sets the map for future AI regulation — from internal checks and coordination among democratic countries to international norms — which makes it easier for readers to understand where control over frontier models is heading.
What is still unknown / limitations
The statements that recursive self-improvement has already begun and the scenario of a persistent botnet with hundreds of billions of dollars in damage are Amodei's own assessments, not reproducible results: methodologies, internal data, and calculations are not disclosed in the sources. The technical protocol of the program, the composition of auditors, and evaluation criteria have not been published, and the operational connection between AI Safety Levels and the actions of external auditors is not described in the sources. It is still unclear whether access will actually be provided and whether the publication of findings will be filtered: this check will be given by the first independent reports. It is also unclear how exactly OpenAI's promises and Hugging Face's request will be concretized.
Sources
- We Must Pace the Frontier — Dario Amodei
- ‘We must slow the pace’: CEO of Anthropic calls for an AI slowdown — The Guardian
- Dario Amodei proposes three-step strategy for responsible AI development — Crypto Briefing
Author
Look at AI, editorial team