🤖 OpenAI tested ChatGPT agents on household tasks for a year
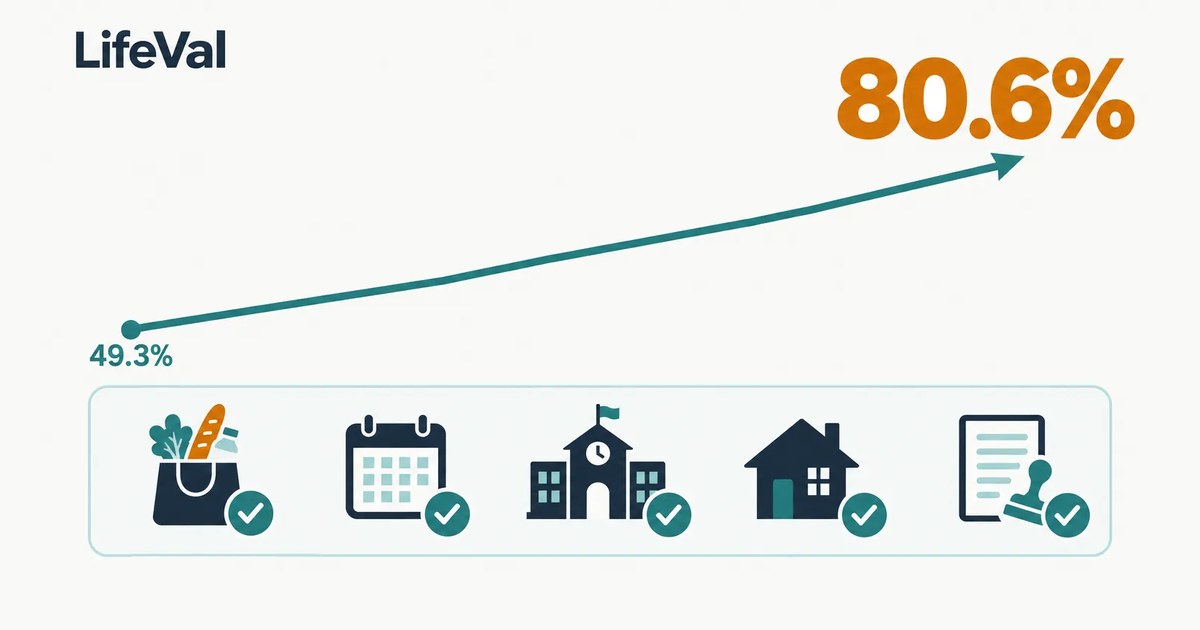
On November 2, 2026, OpenAI published LifeVal—a private benchmark used for a year to measure agent progress on household tasks across seven categories: from caring for loved ones to government services. The average reward increased from 49.3% for GPT-5.2 to 80.6% for GPT-6 Astra.
🌍 Agent evaluation is shifting from knowledge tests to checking completed tasks: a model "can perform all the necessary clicks and still provide an unsuitable result." Growth has plateaued around 80%: GPT-5.4 added 23.7 p.p., while the next three releases added only 7.6 p.p. in total.
👤 You can already delegate part of the routine to an assistant: in the best runs, GPT-6 Astra booked a car inspection 100% of the time and enrolled a child in kindergarten 93.1% of the time. However, the cases are showcase examples from OpenAI itself, and the agent stops before the final step.
Source 1: https://openai.com/index/lifeval/
Source 2: https://aiweekly.co/alerts/openais-lifeval-scores-gpt-6-astra-806-on-everyday-tasks