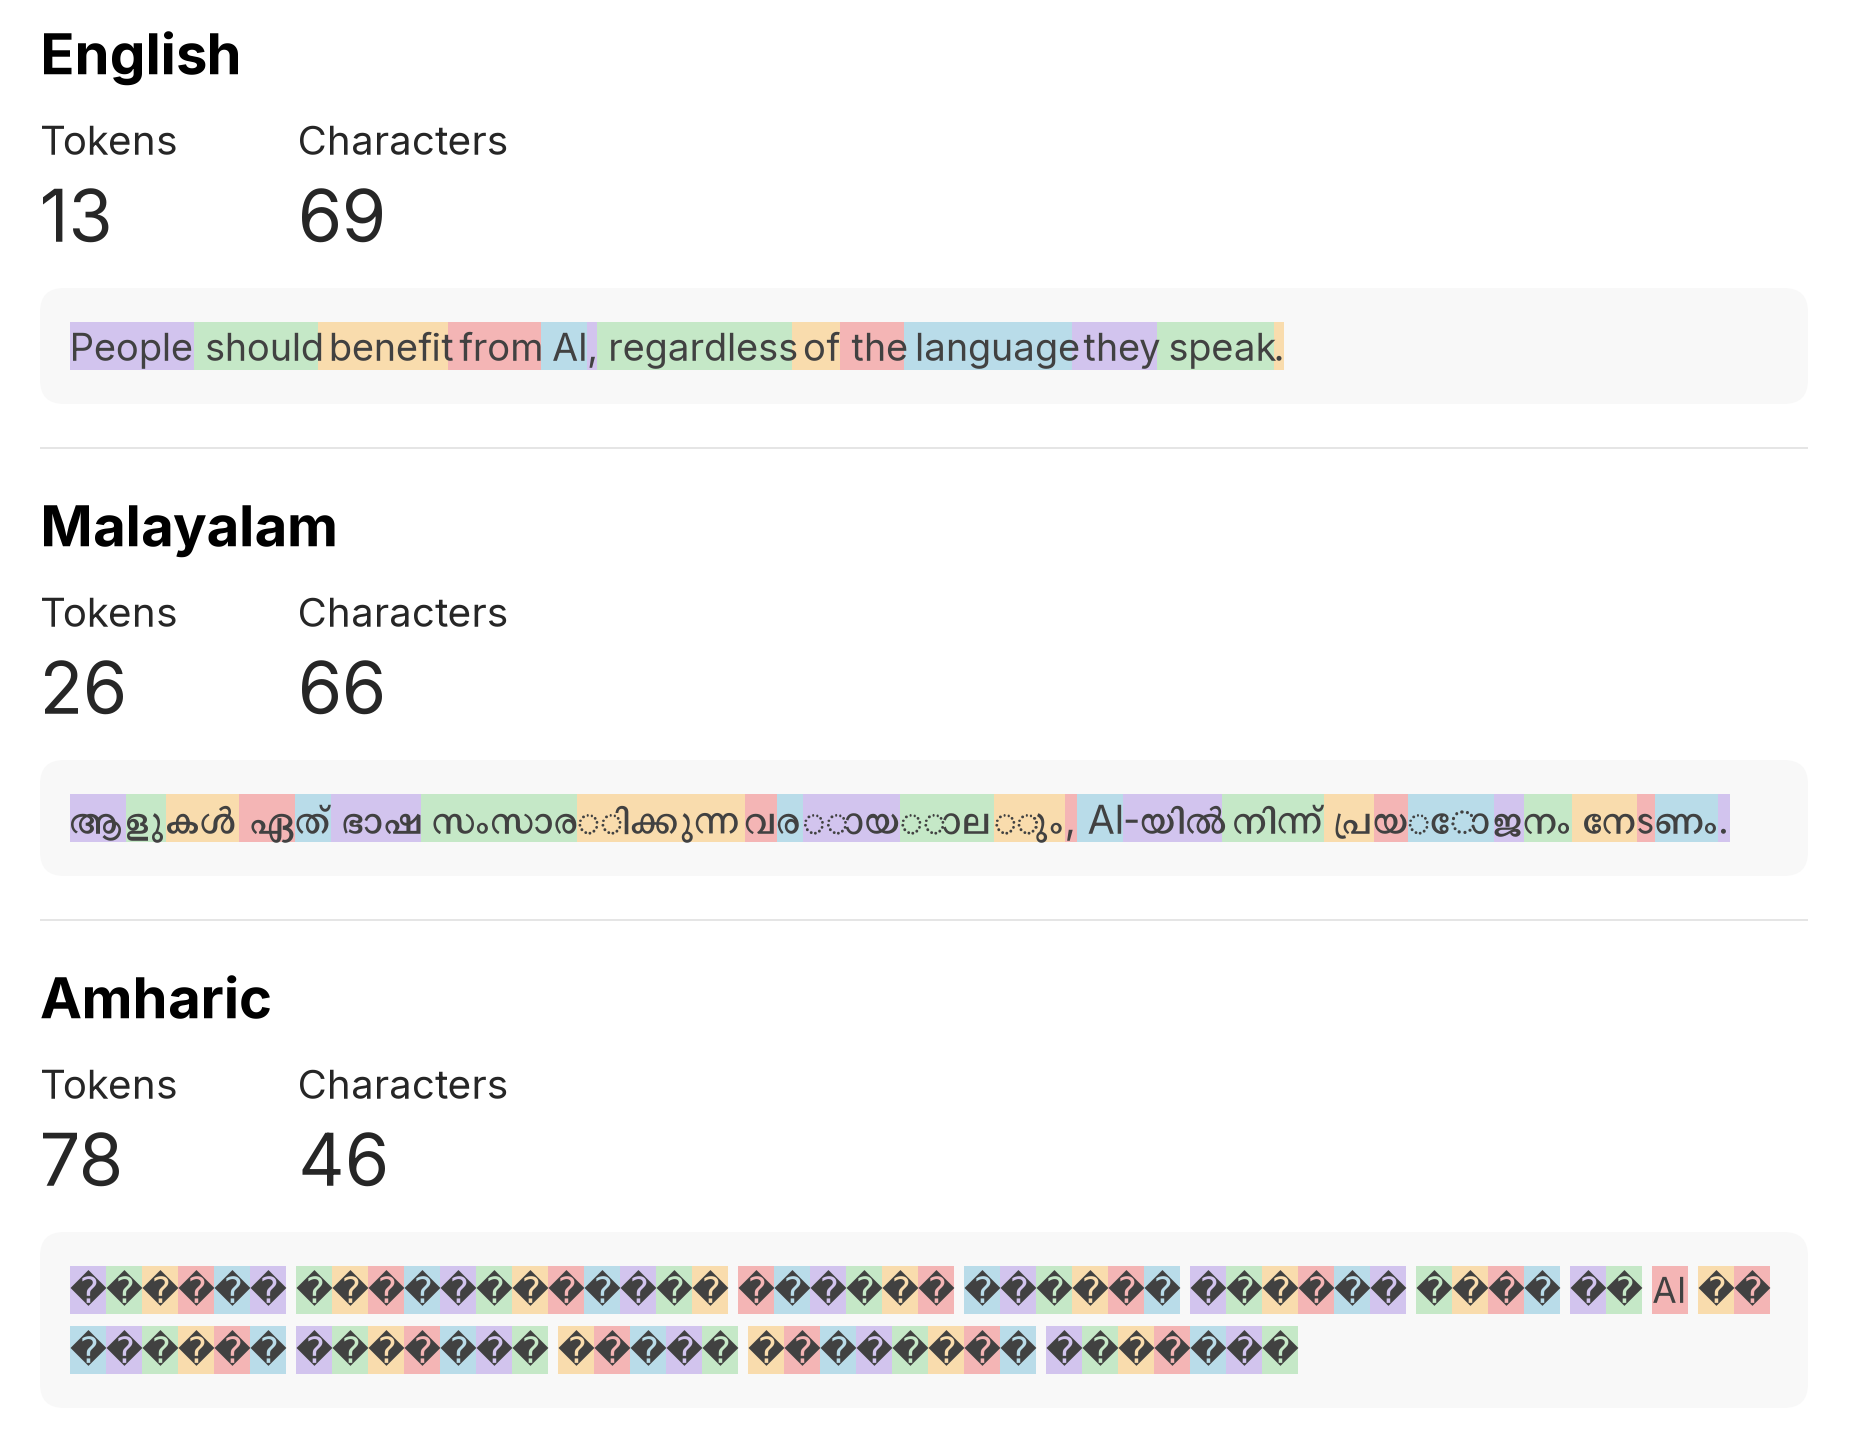
🤖 CLEAR measures the tokenizer tax across different languages
The CLEAR consortium published the study *The Tokenizer Tax* on September 29: LLM tokenizers, trained primarily on English, break text in other languages into more tokens, and APIs charge by the token — the same meaning costs more. On FLORES-200, a phrase is 13 tokens in English for GPT-5, 26 in Malayalam, and 78 in Amharic.
🌍 On the max/min scale, only Meta’s NLLB-200 receives an A (2.7x), Gemini gets a B (5.1x), GPT-5 and gpt-oss get an F (13.8x), and Falcon 3 has a spread of 17x. This metric can be published in model cards, used to expand vocabularies, and to normalize prices.
👤 For RAG and agents using LLM APIs with non-English documents, cost and effective context length depend on the language of the prompts. Measuring a single phrase is an illustration; distributions are needed for estimates.
Source 1: https://clear-languages.org/blog/the-tokenizer-tax Source 2: https://restofworld.org/2026/ai-tokenizer-tax-non-english-languages-cost-inequity/