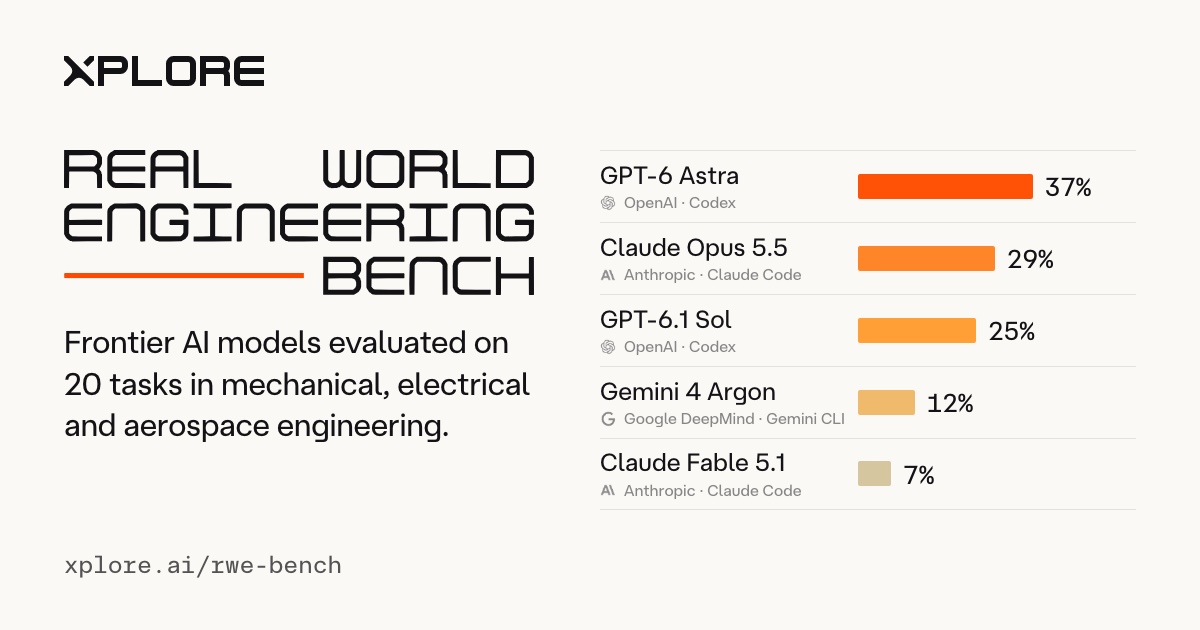
🤖 RWE-bench: Testing AI Models on Real-World Engineering Tasks
Startup Xplore released a closed benchmark consisting of 20 engineering tasks: mechanics (9), electronics (5), and aerospace (6). The model must produce a working design in a sandbox with CadQuery, Gmsh, CalculiX, and Python, which is then checked by an automatic verifier using physics solvers—without a human or LLM judge.
🌍 The niche for human engineers is not closed: the best-performing GPT-6 Astra solves 37% of tasks ($58.83 per run), Claude Opus 5.5 — 29%, and GPT-6.1 Sol — 25%. Four out of 20 tasks were not solved by any of the 11 models across 1,100 runs.
👤 “The model designs like an engineer” is currently just marketing: DeepSeek V4.1 Flash and four other models solved zero tasks. For engineering, GPT-6.1 Sol is more rational in terms of price and quality, and results can be verified on the open EngiWorld: 1,301 tasks, with Claude Opus 5 scoring 44.7 out of 100.
Source 1: https://xplore.ai/rwe-bench Source 2: https://engiworld.github.io/