🤖 Stanford Hazy Research: Text Generation 21 Times Faster Than Diffusion
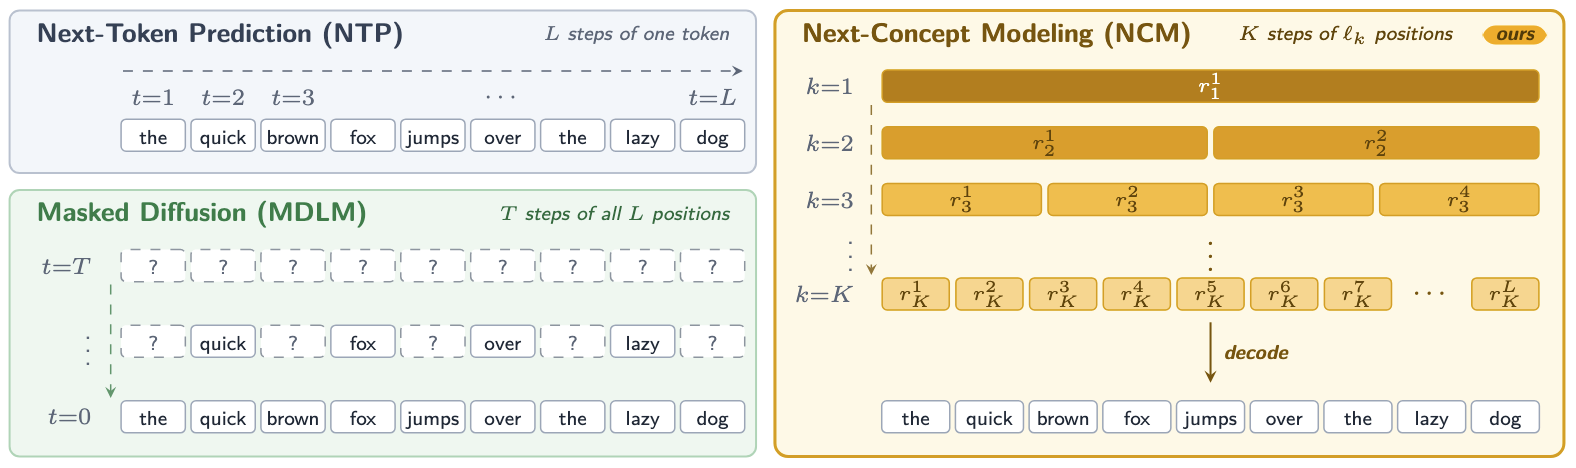
The Stanford Hazy Research team introduced the non-autoregressive framework Next-Concept Modeling (NCM): the model builds a hierarchy of discrete codes from rough "concepts" to details and predicts all codes at a level in parallel.
🌍 A third path between autoregression and diffusion LMs: on a single NVIDIA H100, NCM generates 10–31 times faster than diffusion baselines (21 times on LM1B) with comparable quality, while training requires 4–5 times fewer tokens. Inference—a key growing expense for LLM services—becomes cheaper.
👤 Verifiable on a single H100: code is under MIT license, and weights and datasets (XSum, WMT14 De-En, Sudoku, and others) are open on GitHub and Hugging Face. In reasoning tasks, NCM solves 99.5% of easy and 86.1% of hard boards, compared to 14.6% and 1% for autoregressive models.
Source 1: https://hazyresearch.stanford.edu/blog/2026-10-12-ncm Source 2: https://arxiv.org/abs/2610.14162