🛠 MiniMax H3: A Wave of Third-Party Tools
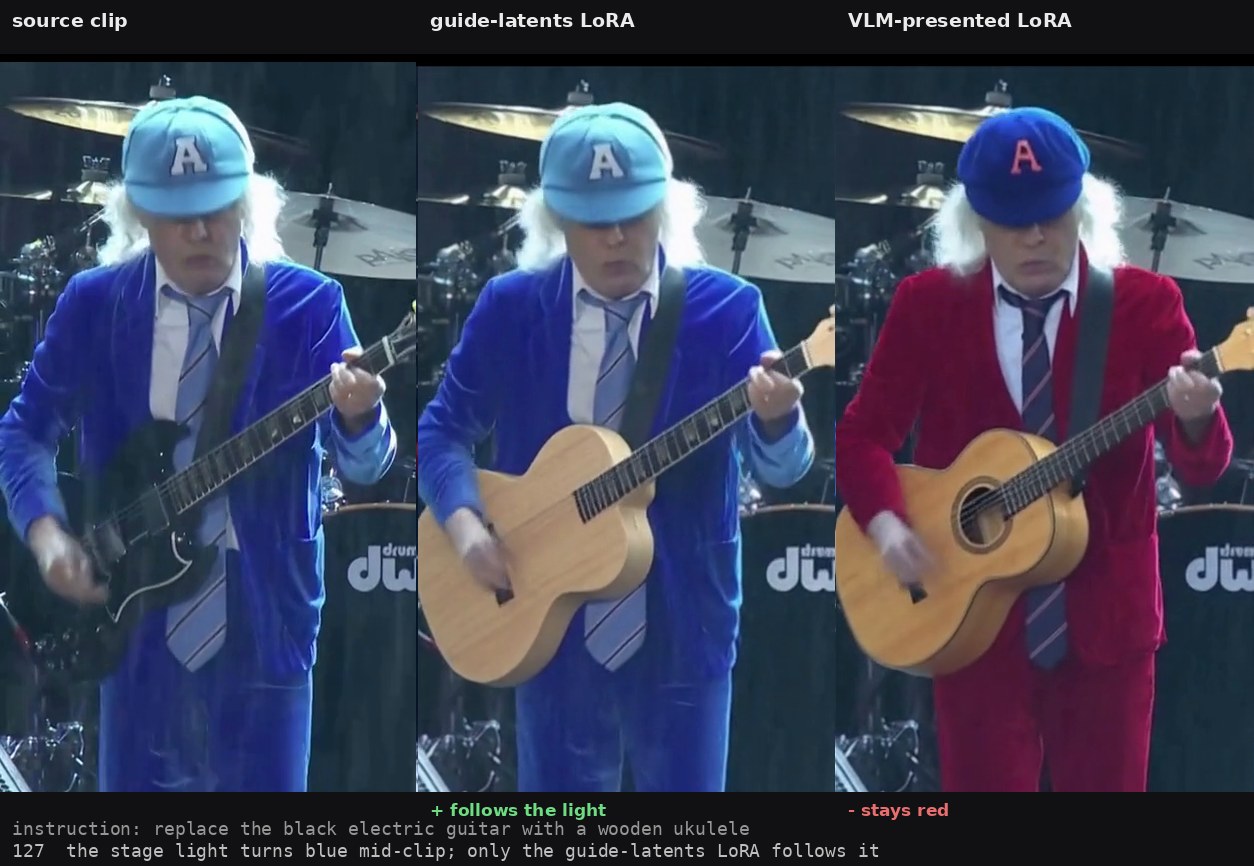
Around the open video model MiniMax H3, VDN-Minimax-H3 distillation (8 steps, ~3× faster than dense H3), TensorRT-VAE for ComfyUI (decoding up to ×1.7), and an ai-toolkit patch with an aligned V2V guide and a ~1 GB dataset instead of ~105 GB have been released.
🌍 In days, the ecosystem replicated the full open-model cycle — distillation down to 8 steps, decoder acceleration, and 114 LoRAs. 768p generation is faster than playback (11.23 s for 14.4 s), moving video diffusion into interactive scenarios. VDN weights are open, but the license excludes the US, EU, UK, and South Korea.
👤 Everything is available today: TRT-VAE delivers up to ×1.7 decoding speedup, LoRAs for VHS aesthetics and micro-expressions are on Hugging Face, the H3-LongVideos workflow is in a ZIP, and the patch provides a synchronous V2V guide and an embedding cache of ~0.9 MB instead of 84 MB.
Source 1: https://huggingface.co/OpenVDN/vdn-minimax-h3 Source 2: https://gist.github.com/alisson-anjos/b300f2b90e65cf85846519d78b660cd3