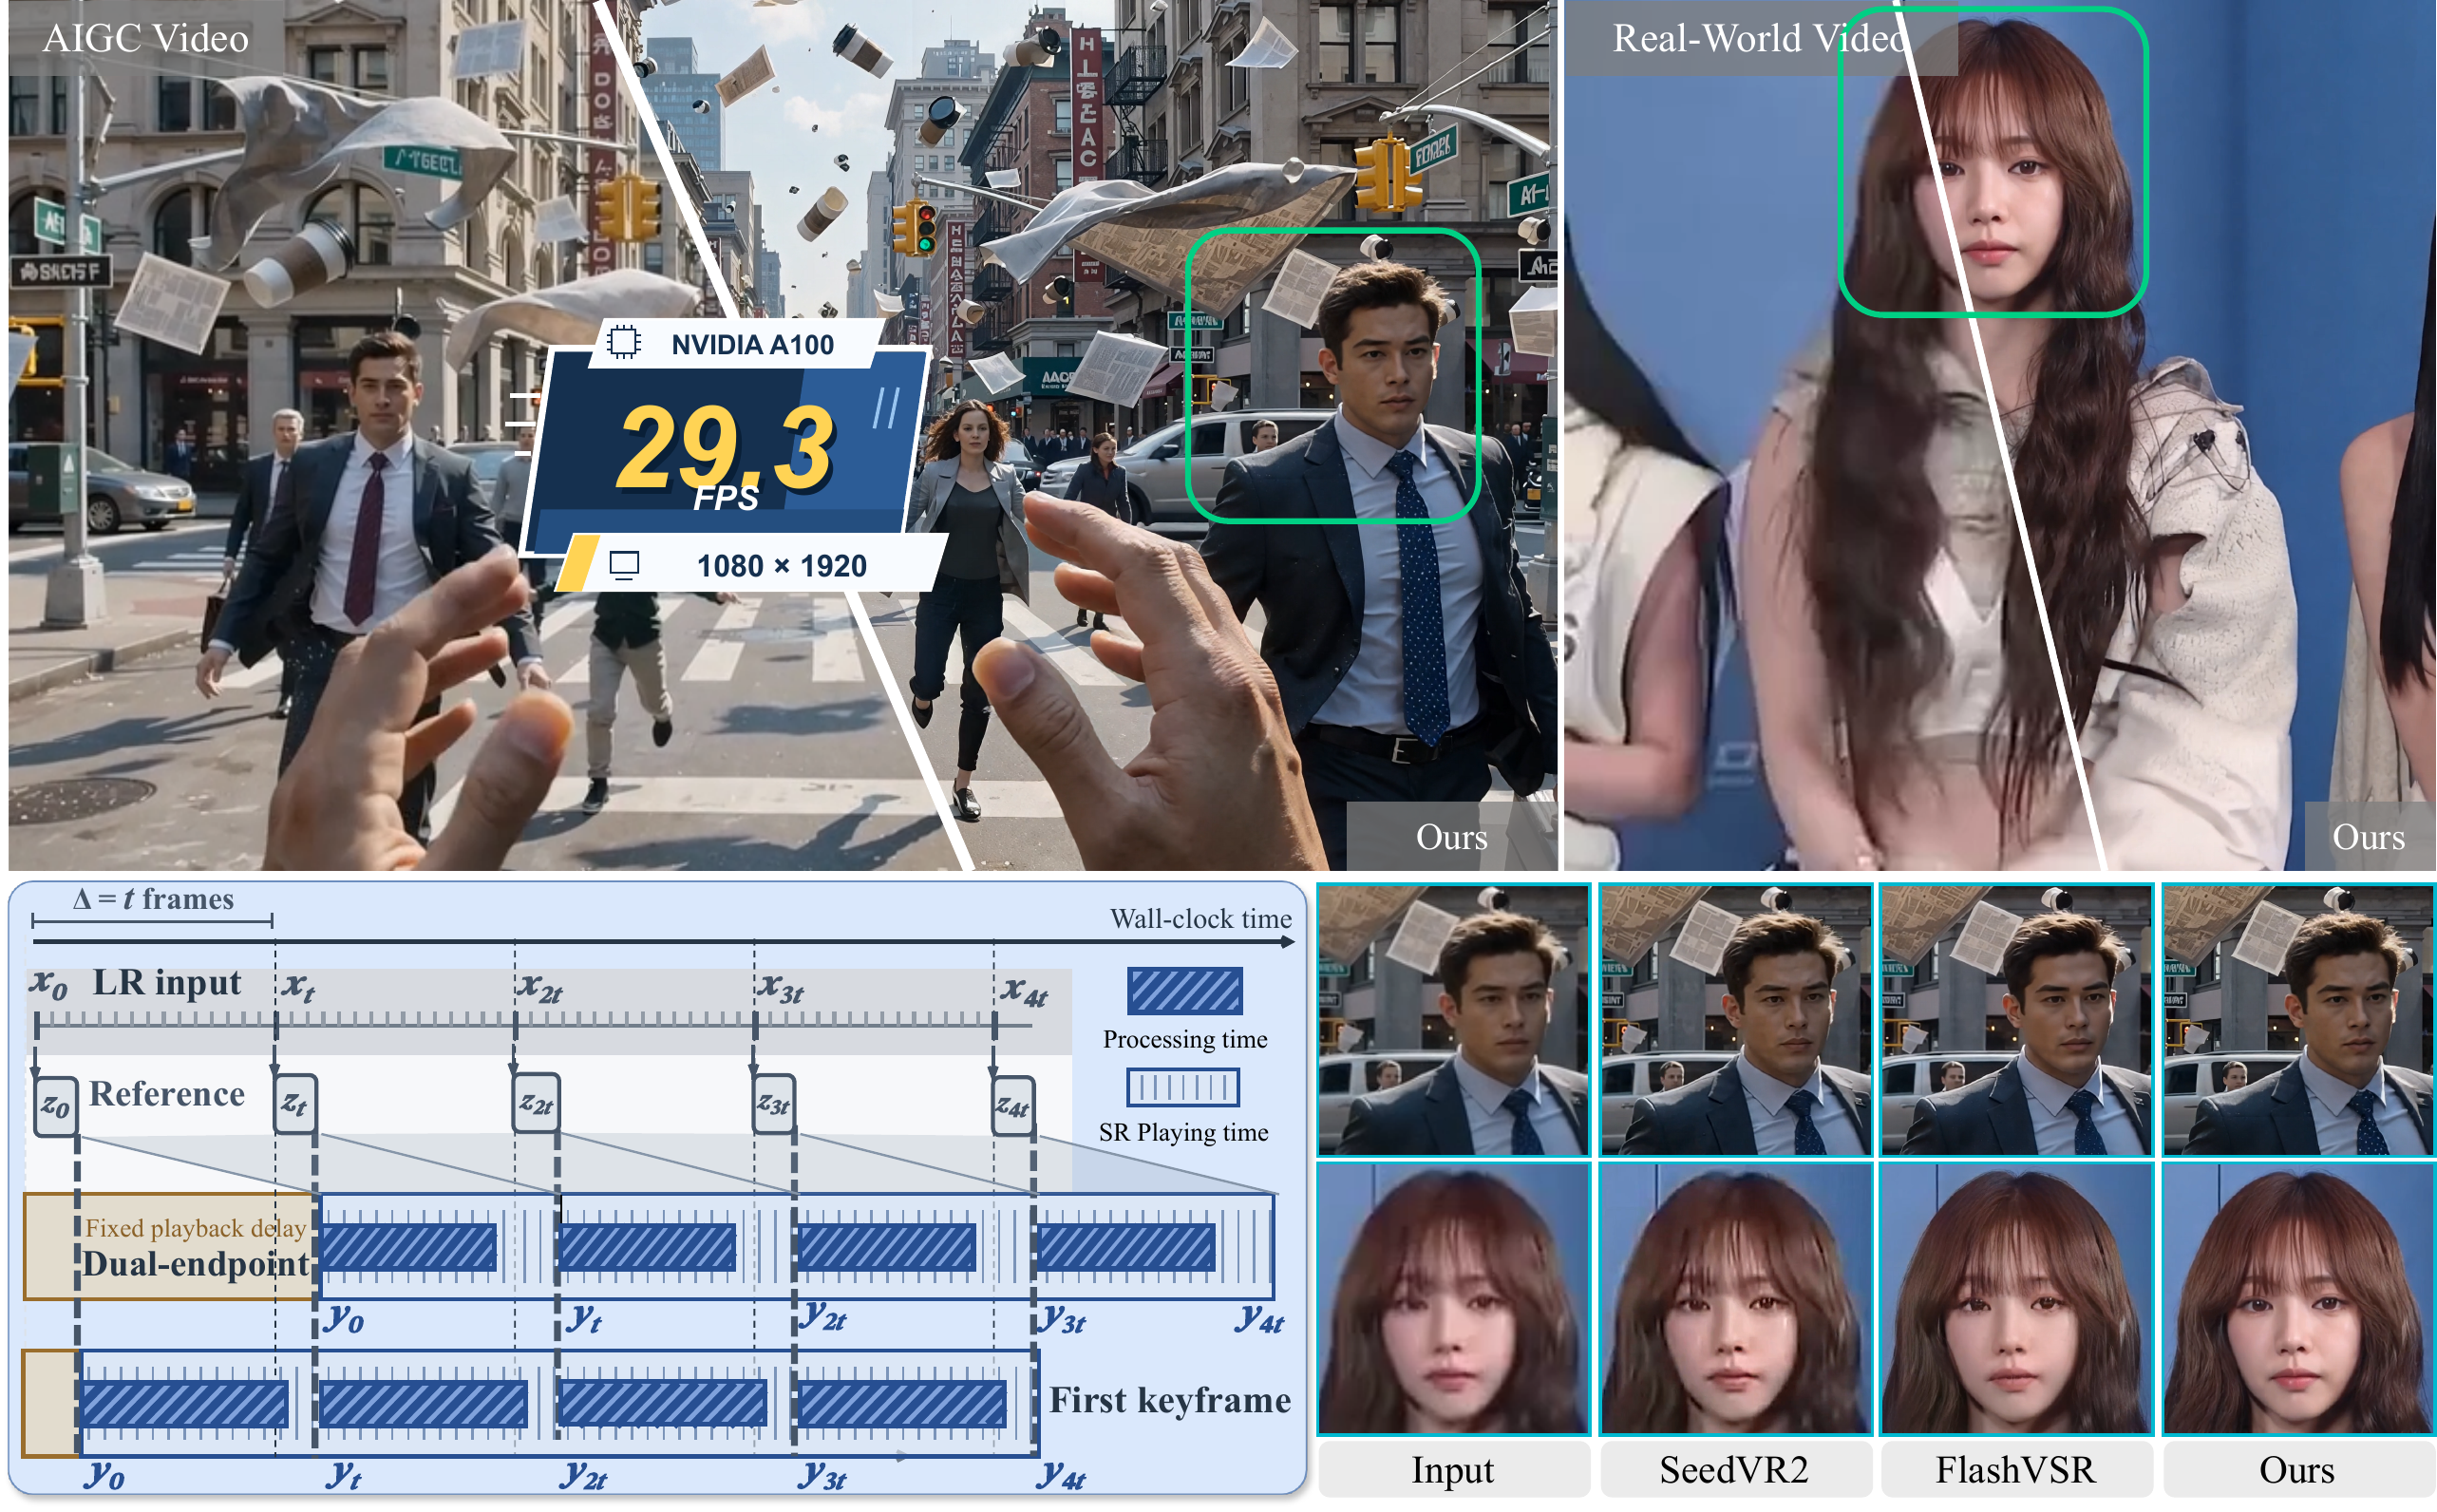
Researchers from the University of Science and Technology of China presented RelayVSR, a streaming framework for 4x video upscaling where a large generative model based on Wan creates reference frames only at rare points in the video, while a lightweight Dual-Memory Video Transformer network reconstructs all other frames. According to the authors' measurements, on a single A100 at 1080p, the framework delivers approximately 29 FPS with 13.82 GB of memory consumption and a first-frame latency of 0.327 seconds, significantly outperforming FlashVSR-Tiny. The code and weights are open under the Apache-2.0 license, and a ready-made ComfyUI port is available, allowing the claimed figures to be verified on your own material.


What happened
A group of authors from the University of Science and Technology of China (Xijun Wang, Xin Li, Zirui Lang, Suhang Yao, Haoran Li, Zhibo Chen) published a preprint arXiv:2609.37850 on 29.09.2026, describing RelayVSR, a streaming framework for 4x video upscaling. The key mechanism is named Sparse Generative Relay: a large generative model based on Wan constructs reference latents only on rare keyframes, while a lightweight Dual-Memory Video Transformer network reconstructs all other frames, relying on the references and recent context. Training is conducted via the VARO scheme, reinforcement learning with two rewards: the system reward evaluates the final video assembled by the lightweight network, while the reference reward evaluates the quality of the keyframes themselves. On a single A100 at 1080p, the framework shows 29.29 FPS with 13.82 GB of memory and a first-frame latency of 0.327 seconds, whereas FlashVSR-Tiny in the provided comparison delivers 7.80 FPS with 24.447 GB and 2.83 seconds to the first frame. The framework operates in streaming modes with reliance on the first frame and on both ends with limited look-ahead, so long videos are processed without being split into chunks. The code is available on github.com/kopperx/RelayVSR under the Apache-2.0 license, weights are hosted on huggingface.co/kopper/RelayVSR, and the ComfyUI port Comfy-Org/RelayVSR has already accumulated over 2,600 downloads.
Context
To understand the value of the scheme, it is useful to recall how a classic generative VSR is structured: a heavy network is run on every frame, resulting in high quality, but time and memory make such a solution suitable primarily for offline processing, where a long video is cut into chunks and one waits for the finished result. RelayVSR redistributes the load differently: expensive calls to the generative model are made rarely and fall on reference frames encoding the main details, while intermediate frames are completed by a lightweight network with memory of recent context. A specific vulnerability of relay approaches is that an error in one reference frame is inherited during completion and can spread throughout the video; therefore, the authors train the models with an RL signal for the final video after the lightweight network, rather than for isolated beautiful keyframes. The completeness of the release is also important: research works on generative VSR rarely come out simultaneously with code, open weights, and ComfyUI infrastructure, whereas here specific measurements on a single A100 are attached, moving the discussion from the demo genre to the production verification mode.
Why this matters for the industry
For the industry, the value lies not only in the framework itself but also in the transferable architectural pattern: rare but expensive calls to a large generative model plus frequent calls to a lightweight network with memory, trained via RL on the final artifact. When applied to upscaling, this provides a claimed gain of approximately 3.75 times in speed and approximately 43% in memory, meaning generative VSR ceases to be a purely offline batch task and becomes a realistic candidate for streaming and processing long videos. Independent evaluation begins immediately: the Apache-2.0 code and open weights allow setting up a self-hosted prototype on an A100-class GPU without waiting for an API or service from the developers. If independent checks confirm the figures, waves of integrations into ComfyUI workflows, first service wrappers, and fine-tuning of the lightweight network for niche content should be expected, and in the longer term, attempts to extend a similar scheme to adjacent video tasks like interpolation and video understanding. These are predictions, not established facts.
Why this matters for users
For readers, the release provides a tool that can be verified in practice: their own 1080p videos can be increased four times at a speed close to real-time playback, without waiting for hours of batch processing. The prototype can be assembled in an evening: install the ComfyUI port Comfy-Org/RelayVSR, run both regular filmed and AI-generated video, and compare the results with the current stack. The weights are openly available on Hugging Face, and the Apache-2.0 license allows commercial use, so both a small studio and a single enthusiast can try the scheme. The main constraint is hardware: the measurements were made on an A100, a data-center class card, so a home build will require a GPU with comparable memory headroom.
What is currently unknown / limitations
The measurements are currently author-provided: there are no independent measurements on different hardware and different content in the published materials, so claims like live upscaling of a broadcast or a several-fold drop in the cost of processing an hour of video remain business hypotheses, not established facts. There are also no quality metrics in the materials, so incorporating RelayVSR into production today should only be done as an experimental stage of the pipeline with a custom set of metrics on real content. This is research code without an API, hosting, or SLA. Finally, the memory consumption in the test refers to the level of data-center GPUs: behavior on consumer cards is not shown.
Sources
- RelayVSR: Large-Small Model Collaboration for Efficient Real-World Video Super-Resolution (arXiv:2609.37850)
- RelayVSR — project page (USTC)
- kopperx/RelayVSR — GitHub: framework code (Apache-2.0)
- kopper/RelayVSR — open weights (Hugging Face)
- Comfy-Org/RelayVSR — ComfyUI port (Hugging Face)
Author
Look at AI, editorial team