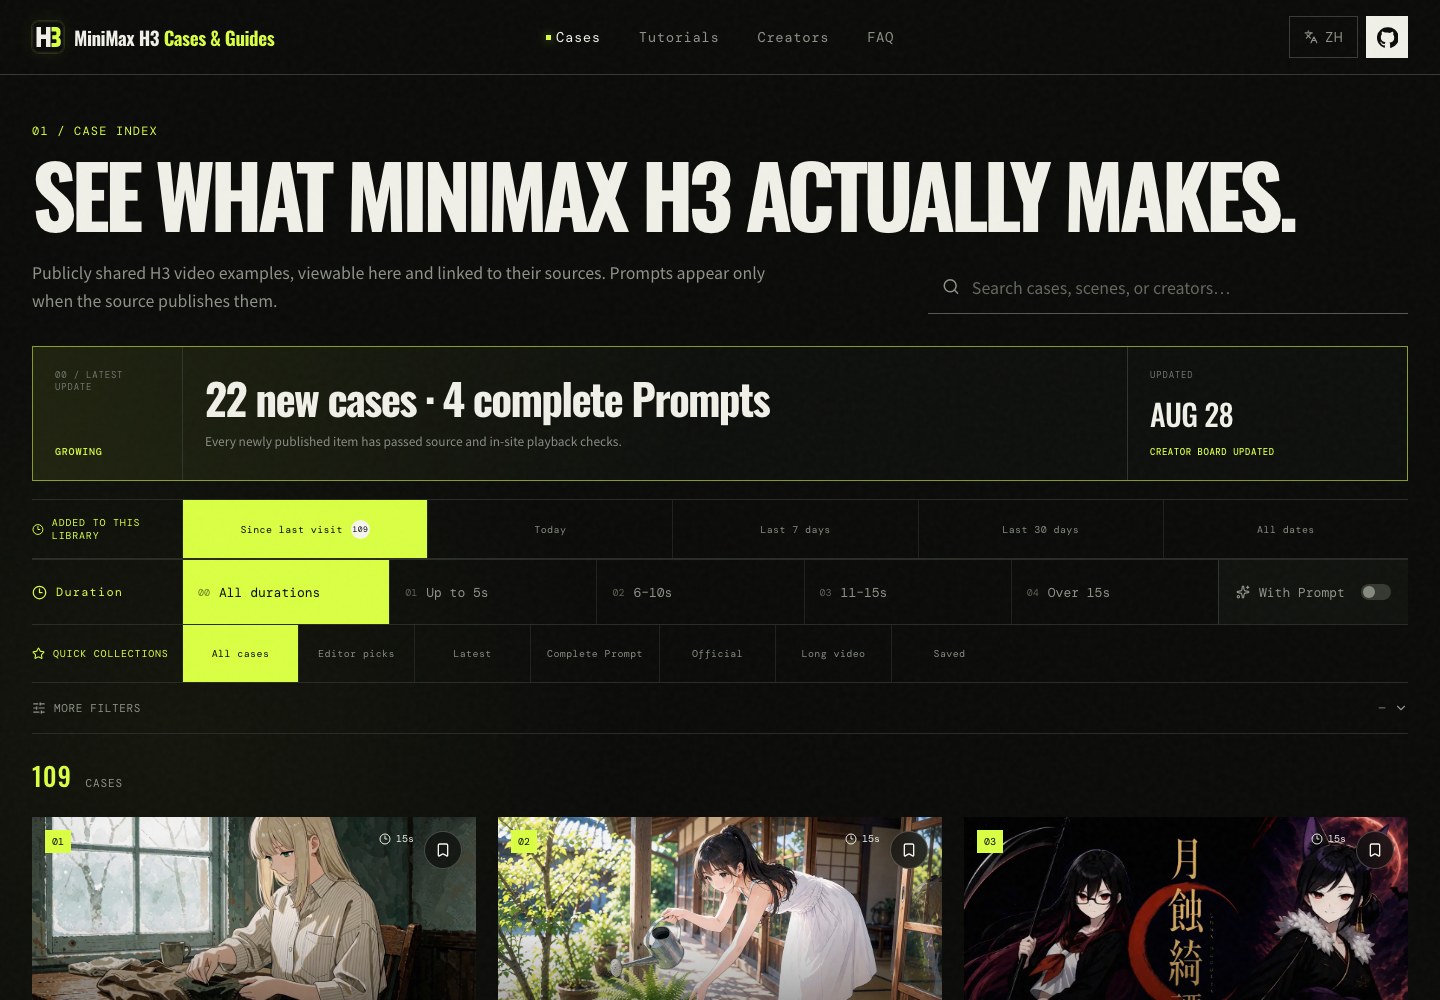
The author of the 'Neuronaut' channel has compiled the seventh part of a collection of tools for the open video model MiniMax H3 (also known as Hailuo 3): nine links to Hugging Face and GitHub, created by the community in August 2026 — all verified and working. The release features a decoder-only VAE that decodes a single frame from an H3 latent and outperforms the official decoder on the PSNR metric, modular diffusers blocks for video and audio inpainting using a single mask, and a rank-16 LoRA against jitter in fast scenes. The set is completed by the awesome-minimax-h3 library with hundreds of ready-made cases and prompts. Everything in the collection can be installed and tried today.


What happened
The seventh collection under the #minimaxH3 tag brings together nine links to Hugging Face and GitHub, created in August 2026; the author notes that all links are verified and working. On Hugging Face, the decoder-only model iamkaikai/MiniMax-H3-Single-Frame-VAE-500K was released: it was trained on 500,000 reconstructions, decodes a single frame from an H3 latent slice, and shows a PSNR of 31.12 dB versus 30.35 dB for the official VAE, meaning a gain of 0.77 dB, with the strongest effect on diagrams, line graphs, and product outlines; the authors immediately clarify that the model is not intended for decoding full video. Also published there are the modular diffusers blocks diffusers-modular/minimax-h3-inpainting: the mask is converted into timesteps of rows in a unified video-audio latent, and the preserved rows are fixed at the 'clean' noise level t=0.999 and act as conditioning. The rank-16 LoRA MATLOWAI/MiniMax-H3-Motion-Adapter is aimed at reducing jitter in fast scenes: the alternation metric drops from 0.370 to 0.134, and motion speed recovery improves from 1.416 to 1.011. The nodes tori29umai0123/ComfyUI-MiniMaxH3-SingleFrame use the rounding rule frame_count % 17 == 5, and the awesome-minimax-h3 library from the collection gathers cases, full prompts, and tutorials for the model.
Context
MiniMax H3, also known as Hailuo 3, is an open video model whose infrastructure is growing primarily through the efforts of the community: the seventh part of the collection in a single month shows the pace of tool accumulation. The model's architecture explains the intent behind these releases. The H3 latent packs video and audio into a single tensor, and it is precisely this packaging that allows a single mask to be applied to both the video stream and the audio track. The frame_count % 17 == 5 rule in the nodes reveals the model's undocumented temporal grid: frames are causally grouped into blocks of 1,4,4,4,4 over a 17-frame period, and this is a rare case where an architectural detail has been restored through the model's behavior rather than open code. Finally, PSNR, on which the VAE comparison is based, measures the pixel-wise closeness of the reconstruction to the original, but not the perceptual quality of the image, so the gain figures should be interpreted with caution.
Why this matters for the industry
For the industry, the seventh collection is a signal of a platform shift: within weeks, the community has closed the functional gaps of the open video model without waiting for official releases — a single-frame decoder with a benchmark, video and audio inpainting, stabilization of fast scenes, and audio nodes. The inpainting mechanism through timesteps of rows in a packed latent is a ready-made recipe for other multimodal diffusion architectures, and the revealed 17-frame grid provides a foundation for specialized adapters with precise frame interpolation and duration control. Operations that previously cost money or were done manually — masking video and audio, motion stabilization, single-frame generation — are becoming free, and basic video capabilities are rapidly being commoditized. However, these are builder tools, not production components: the sources contain no data on latency and throughput. If the pace is maintained, the recipes will migrate to the core of diffusers and ComfyUI, and closing gaps by the community will become a standard channel for the development of open models alongside official releases — but this is an interpretation, not an established fact.
Why this matters for users
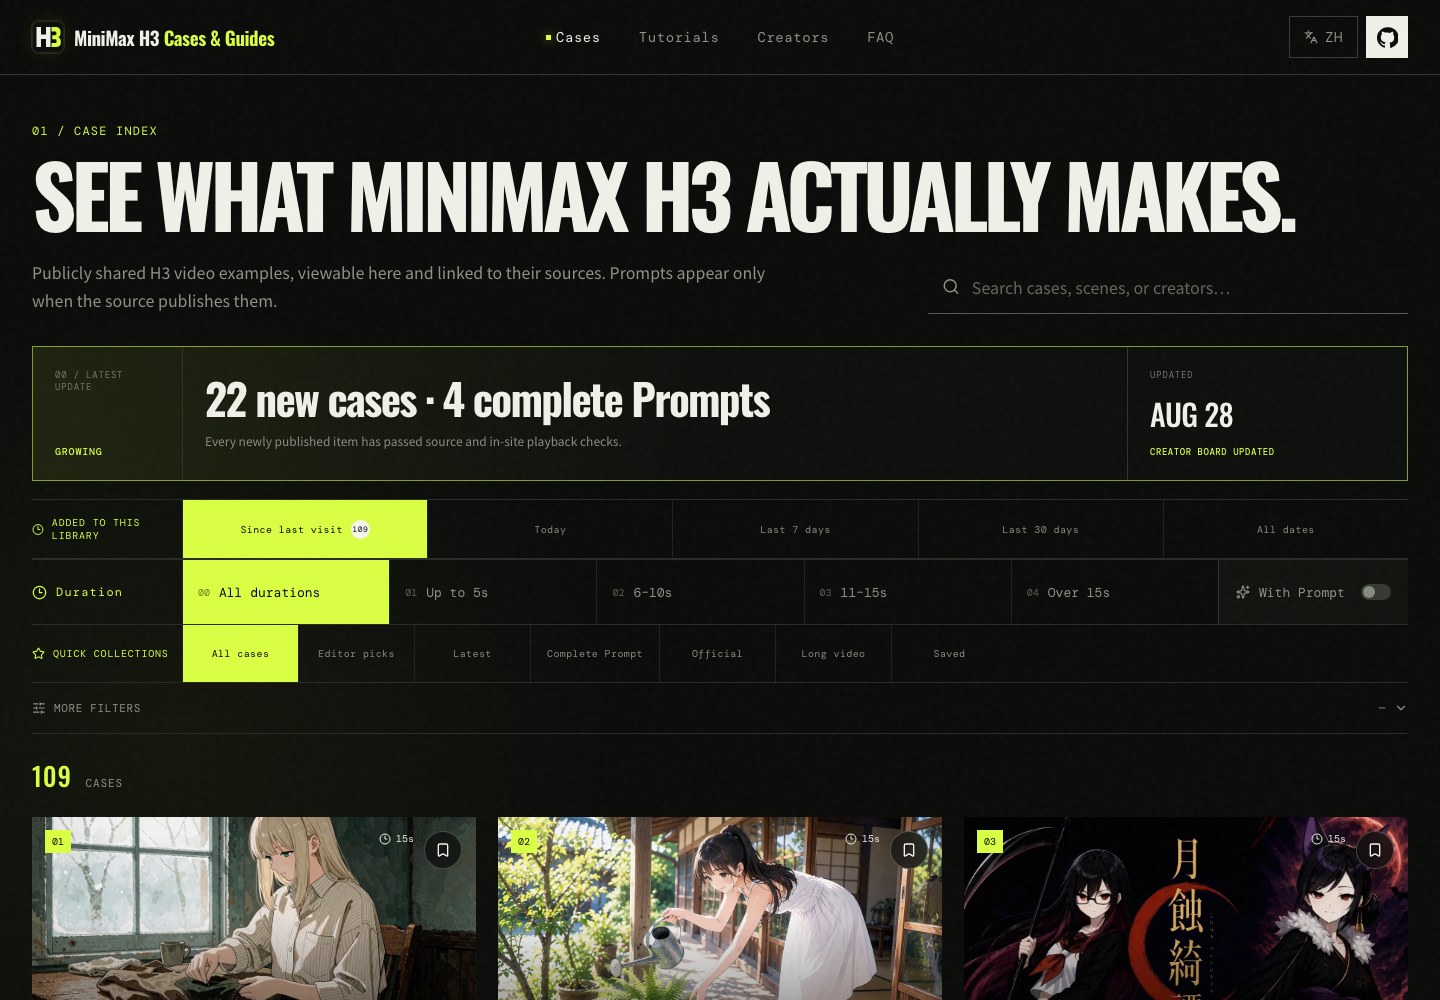
Everything in the collection can be installed and tested on the same day: ComfyUI nodes are installed via Manager or git clone, LoRA and VAE are downloaded from Hugging Face, and inpainting has a ready-made workflow. The fastest entry point is the awesome-minimax-h3 library: 1106 video cases with filters by date added, duration, prompt, and style, 334 full prompts, and 24 tutorials, plus ready-made routes for weak hardware. The practical value right now is single-frame generation, including diagrams and graphs, interpolation of the middle frame between the first and last, local video and audio edits by mask; some routes require only 8–12 GB of VRAM. The tools should be used with known limitations in mind: VAE-500K is not suitable for decoding full video without temporal consistency control, the LoRA should be turned off in calm scenes because it mutes saturated colors, and inpainting is best done with hard rather than feathered masks.
What is still unknown / limitations
The evidence base for quality is currently weak: PSNR is a weak proxy for perceptual quality, and the sources do not include SSIM, LPIPS, or human evaluation, so the advantage of VAE-500K is confirmed by a single metric on limited content types. The Motion-Adapter has quantitative reporting, but the methodology for measuring alternation and motion speed and its comparability with other solutions are not described. The sources contain no data on latency and throughput, so capacity planning is impossible, and the practical ceiling for the tools is prototyping and local pipelines. The 17-frame temporal grid was restored from the model's behavior, not from official documentation, and it should be re-verified on new versions of H3. Predictions about the transfer of recipes to diffusers and the transformation of case libraries into standard eval corpora are interpretations, not verified facts.
Sources
- iamkaikai/MiniMax-H3-Single-Frame-VAE-500K — decoder-only VAE for single frames of MiniMax H3 (Hugging Face)
- diffusers-modular/minimax-h3-inpainting — masked video & audio inpainting for MiniMax H3 (Hugging Face)
- SkyNotSilent/awesome-MiniMax-H3-cases — awesome-minimax-h3 case library with prompts and tutorials (GitHub)
Author
Look at AI, editorial team