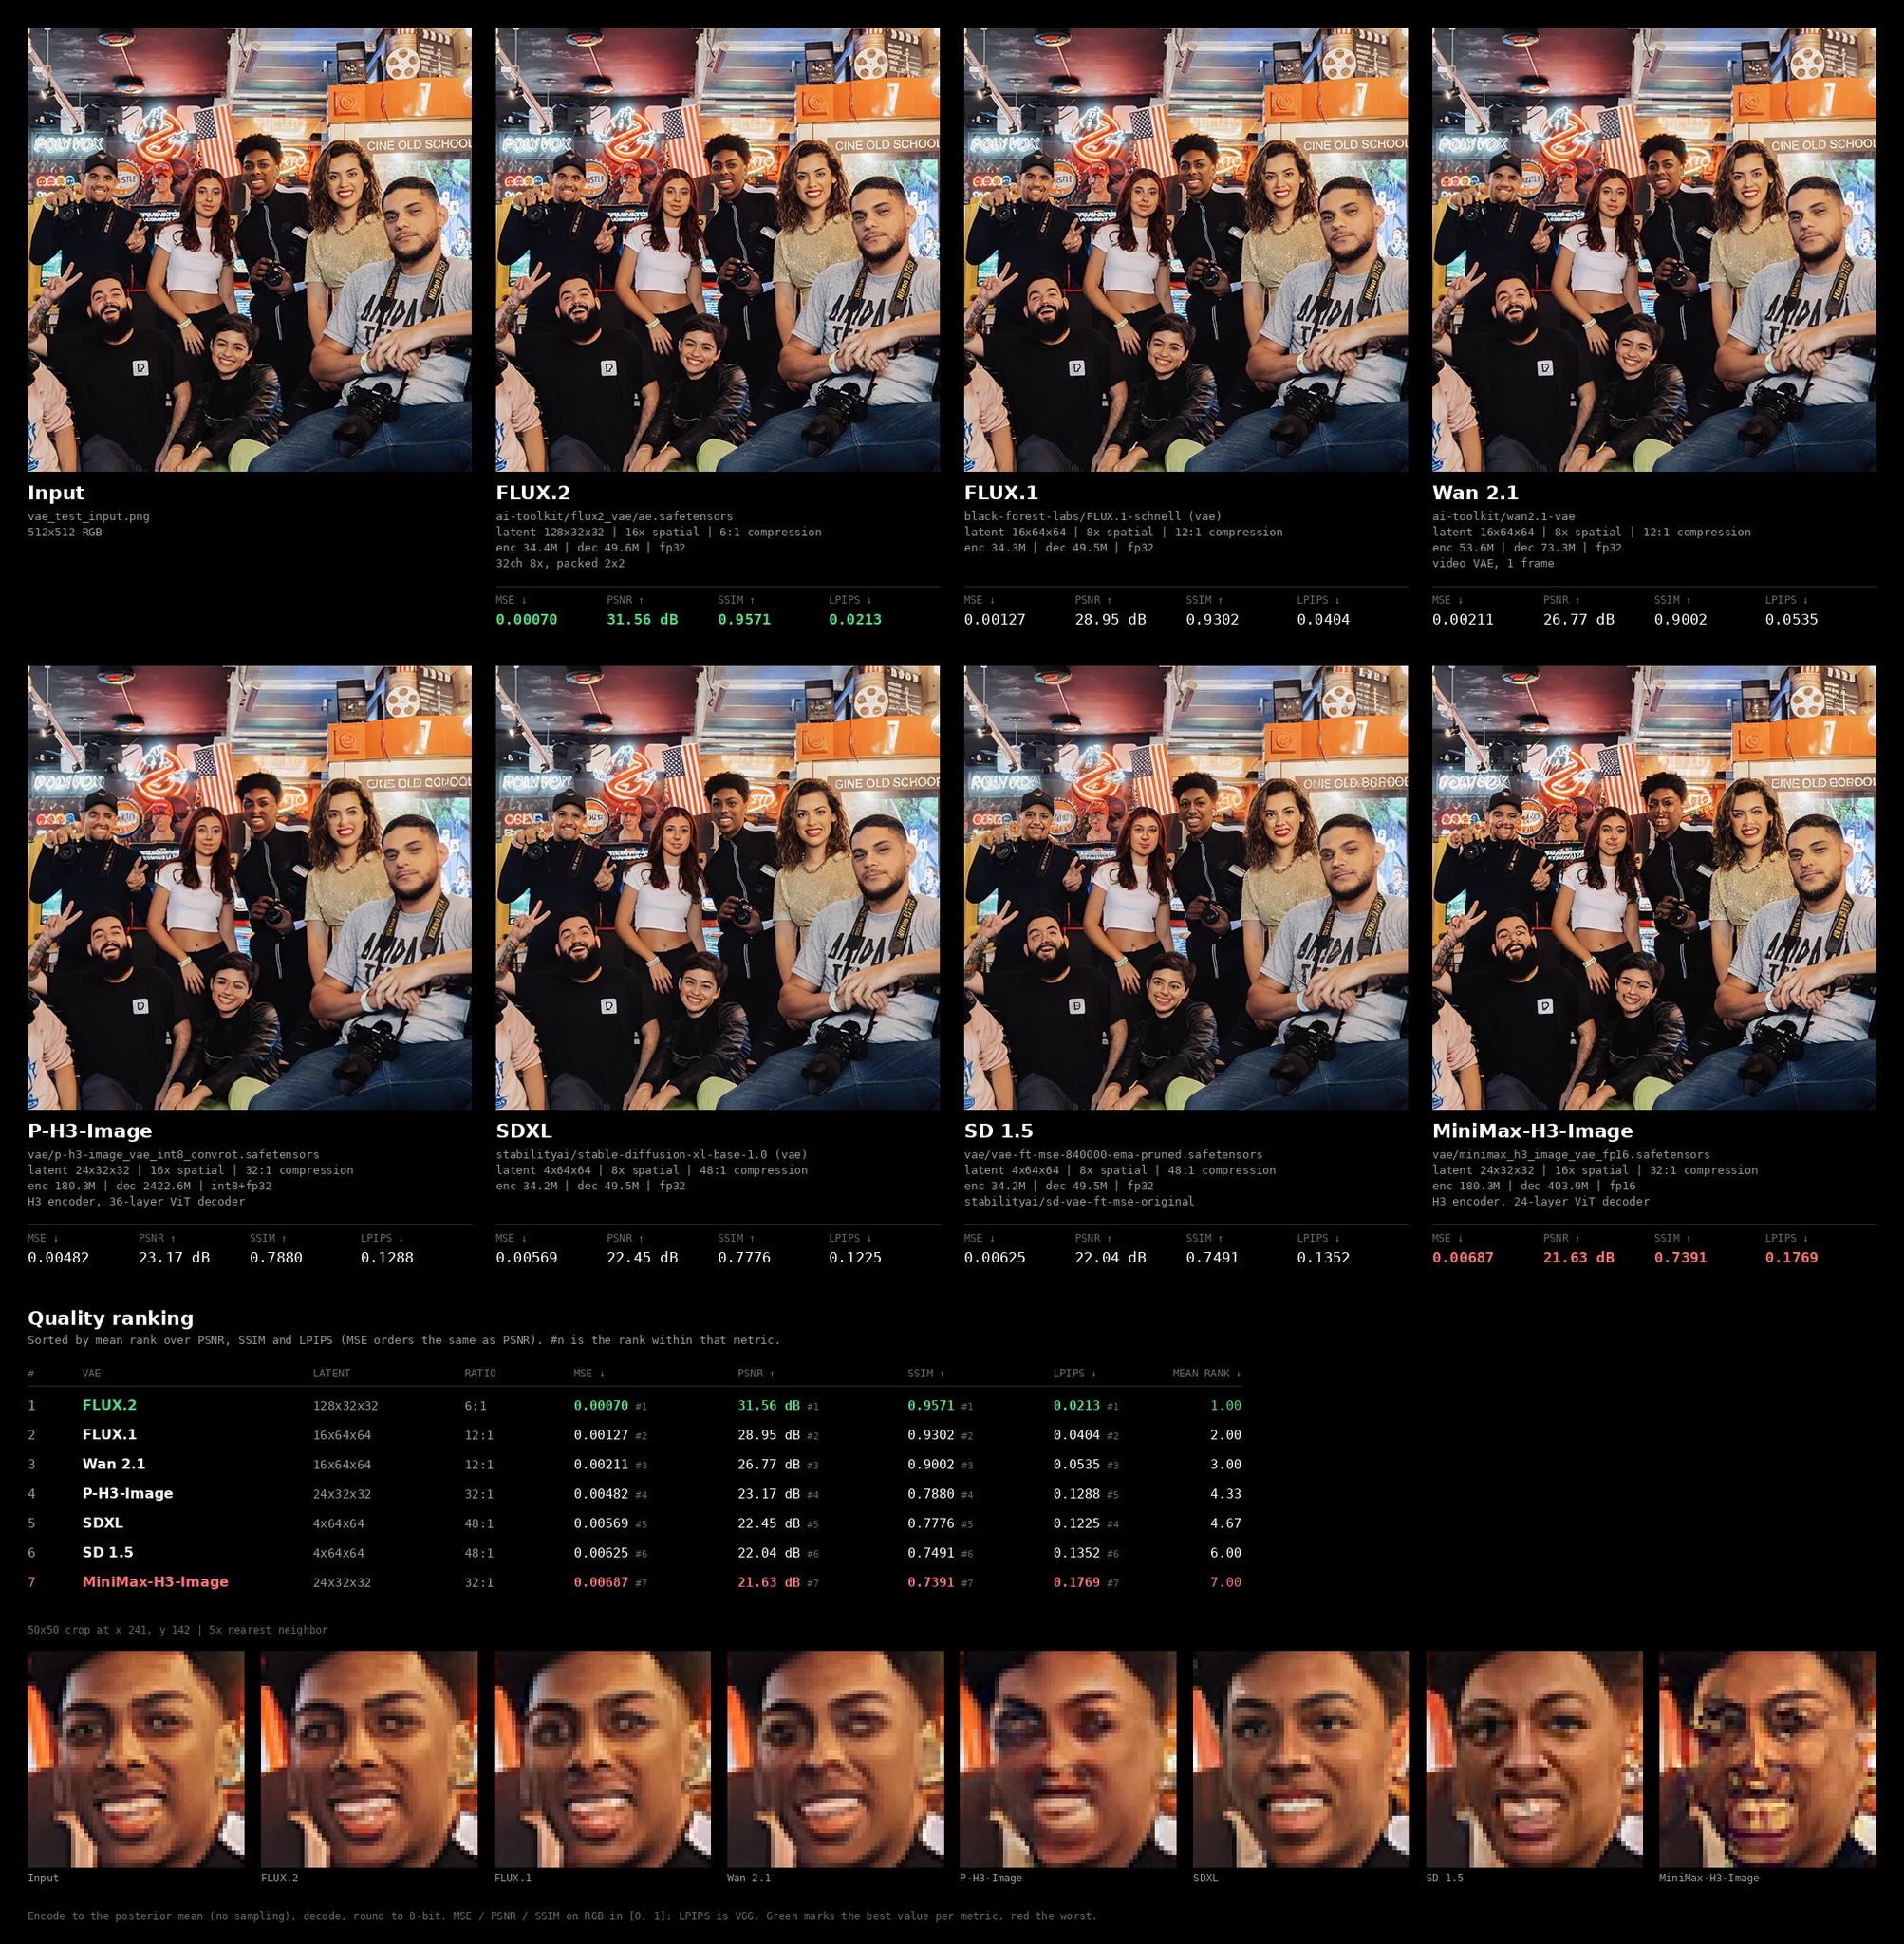
🤖 MiniMax H3-Image Has a Weak VAE
Developer Ostris published a round-trip test of popular VAEs: the MiniMax H3-Image autoencoder (open release on 10.11.2026, 33.1B DiT, claimed 4K/16 MP in 10 seconds) loses on all reconstruction metrics even to the SD 1.5 VAE. The cause is the compressed latent from the H3 video model: 32×32 pixels per token versus 16×16 in Flux.
🌍 The workaround VAE build by Pruna has already garnered ~978k downloads, and Ostris is fine-tuning the decoder. However, swapping the decoder does not recover information lost by the encoder—it only mitigates artifacts.
👤 If you are generating H3-Image in ComfyUI, use the VAE from PrunaAI/P-H3-Image-Comfy (bf16 5.56 GB or int8 3.15 GB), with SA Solver or SGM Uniform samplers, and generate at 16 MP with downscaling. For micro-details (textures, faces, small text), Flux-class models are currently more reliable.
Source 1: https://x.com/ostrisai/status/2120564773150711825 Source 2: https://github.com/MiniMax-AI/MiniMax-H3-Image