🤖 Open Athena Reveals Architecture of Marin 535B-A23B
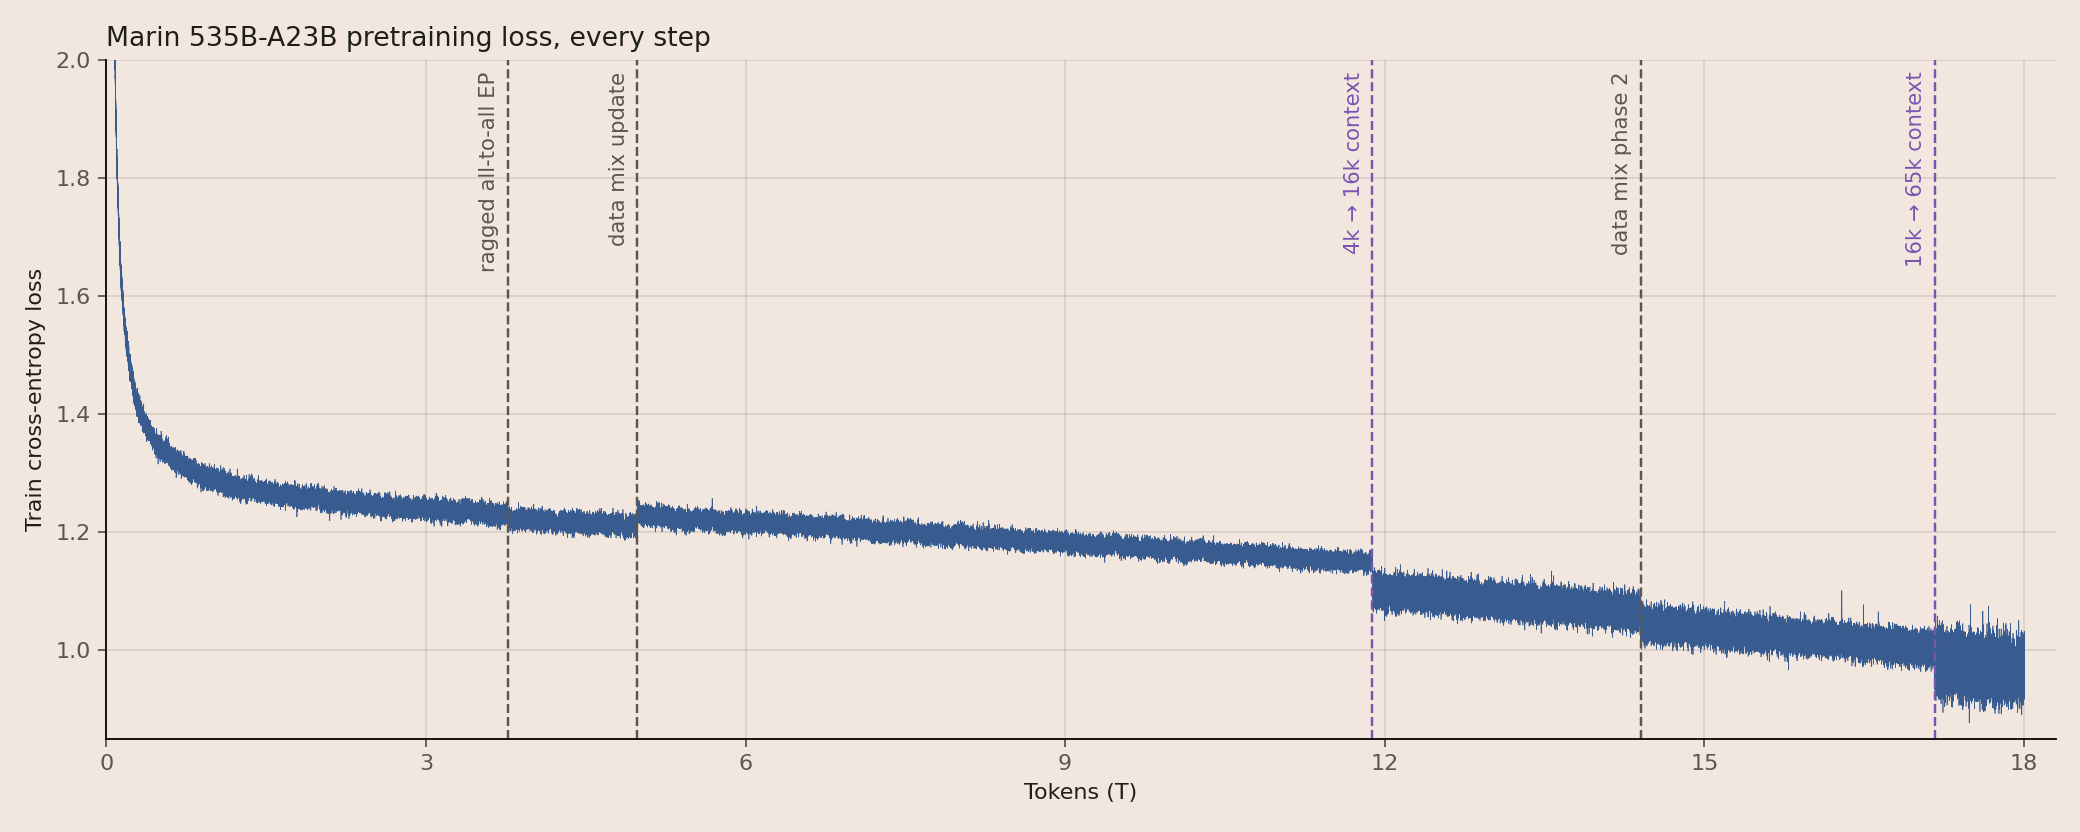
The MoE model with 535 billion parameters and 23 billion active parameters completed pretraining on November 5 using 18 trillion tokens on 768 GB200 GPUs. Paloma macro-loss: 1.982 against a pre-predicted 2.039, with no loss spikes; context grew from 4k to 16k and 65k.
🌍 Public breakdown of large-scale MoE pretraining with numbers: 18T tokens, 768 GB200s, ~1.3x efficiency gain from Expert Parallelism and Latent MoE, drop rate dropped from 5.5–7.1% to ~0.01–0.14%. The industry gets a set of techniques: ragged all-to-all, XSA, SConv, Hyperball optimizer.
👤 It shows how frontier lab problems are solved: token dropping, router stabilization, on-the-fly context expansion. Numbers and graphs are open, and Marin experiments and data are published. The prediction hit proves the predictability of the run, not the superiority of the model.
Source 1: https://openathena.ai/blog/marin-535b-architecture/ Source 2: https://openathena.ai/projects/marin/