🎨 Sber open-sources Kandinsky Avatar 1.0 for talking video avatars
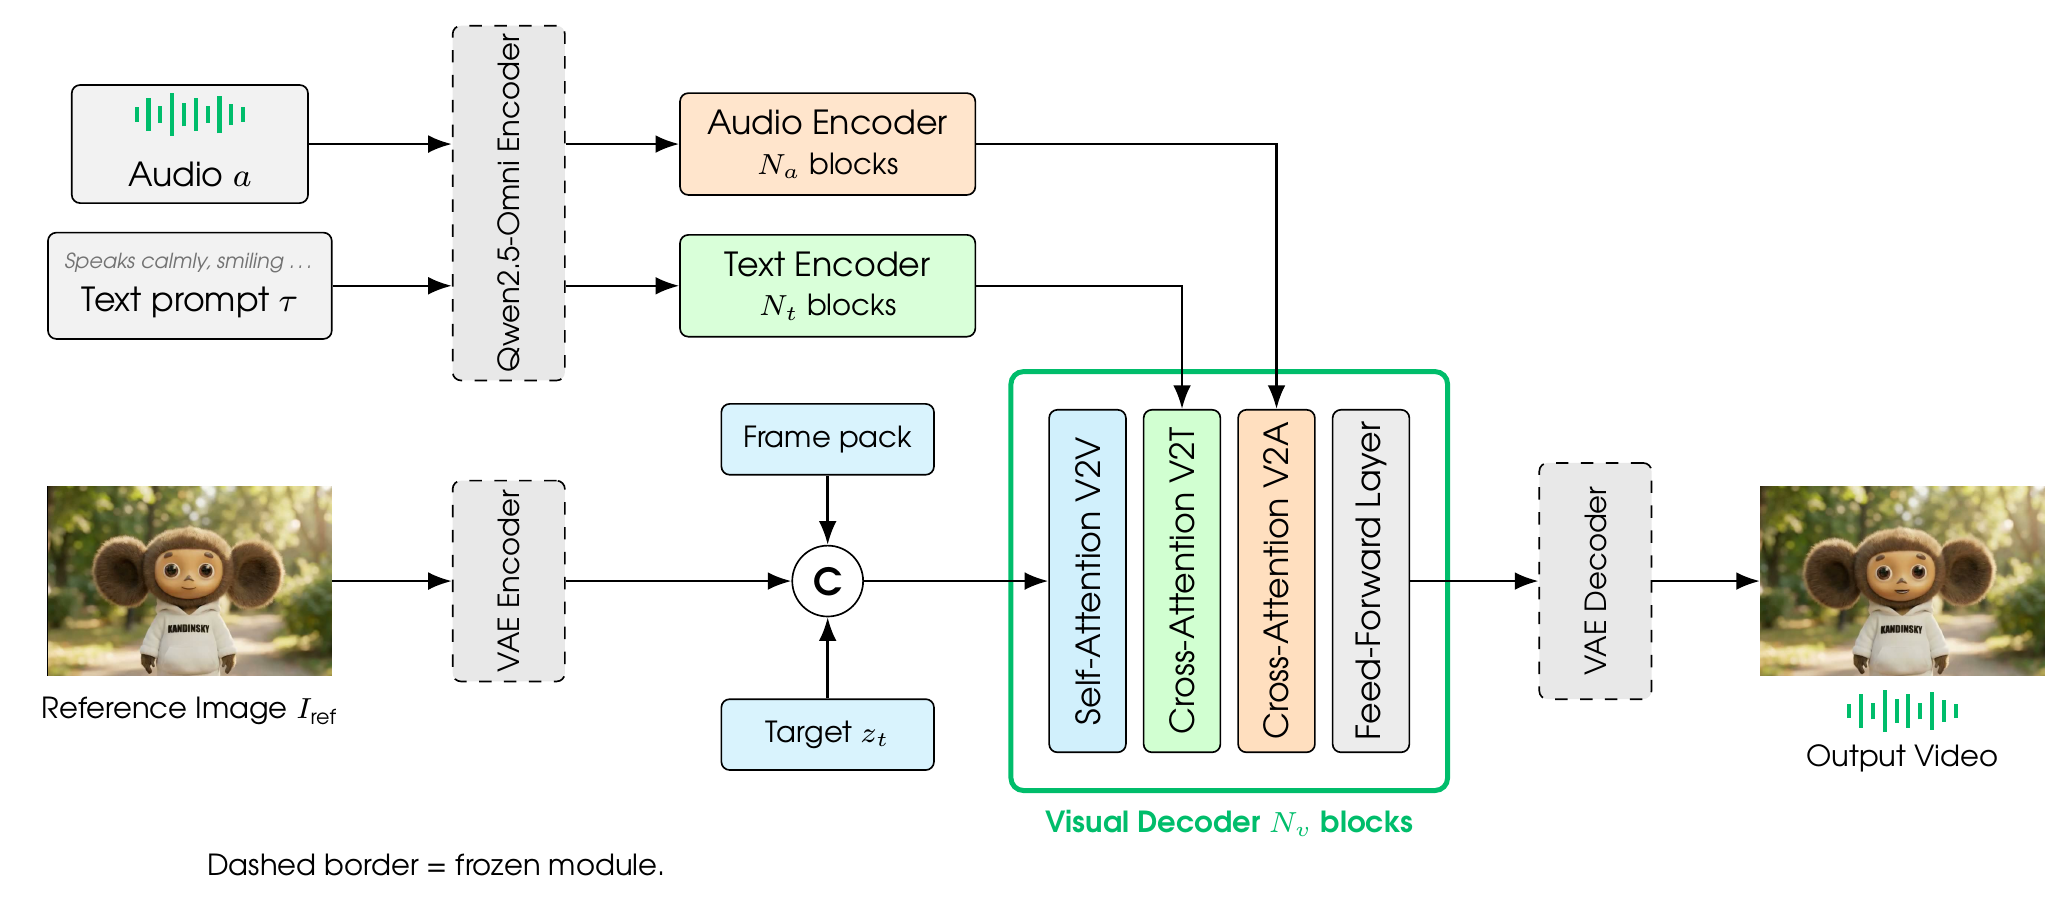
The Kandinsky S2V 1.0 family of speech-to-video models — Lite with 2B parameters and Pro with 21B parameters, plus fast π-Flow versions — has been released under the MIT license: both code and weights are open. From a single reference frame, audio, and text, the model generates 25 FPS video where articulation, facial expressions, and gestures follow the speech, with long videos assembled from 5-second chunks.
🌍 An open MIT alternative to HeyGen and similar services: commercial use is permitted — virtual consultants, training, localization. According to Sber's own blind evaluations, the Pro model is comparable to two commercial models and leads in lip-sync.
👤 A demo is available without installation in the Hugging Face Space Kandinsky-S2V-1.0-Demo; for local deployment, an NVIDIA GPU with 48–80 GB VRAM is required.
Source 1: https://kandinskyavatar.github.io/ Source 2: https://github.com/kandinskylab/kandinsky-s2v