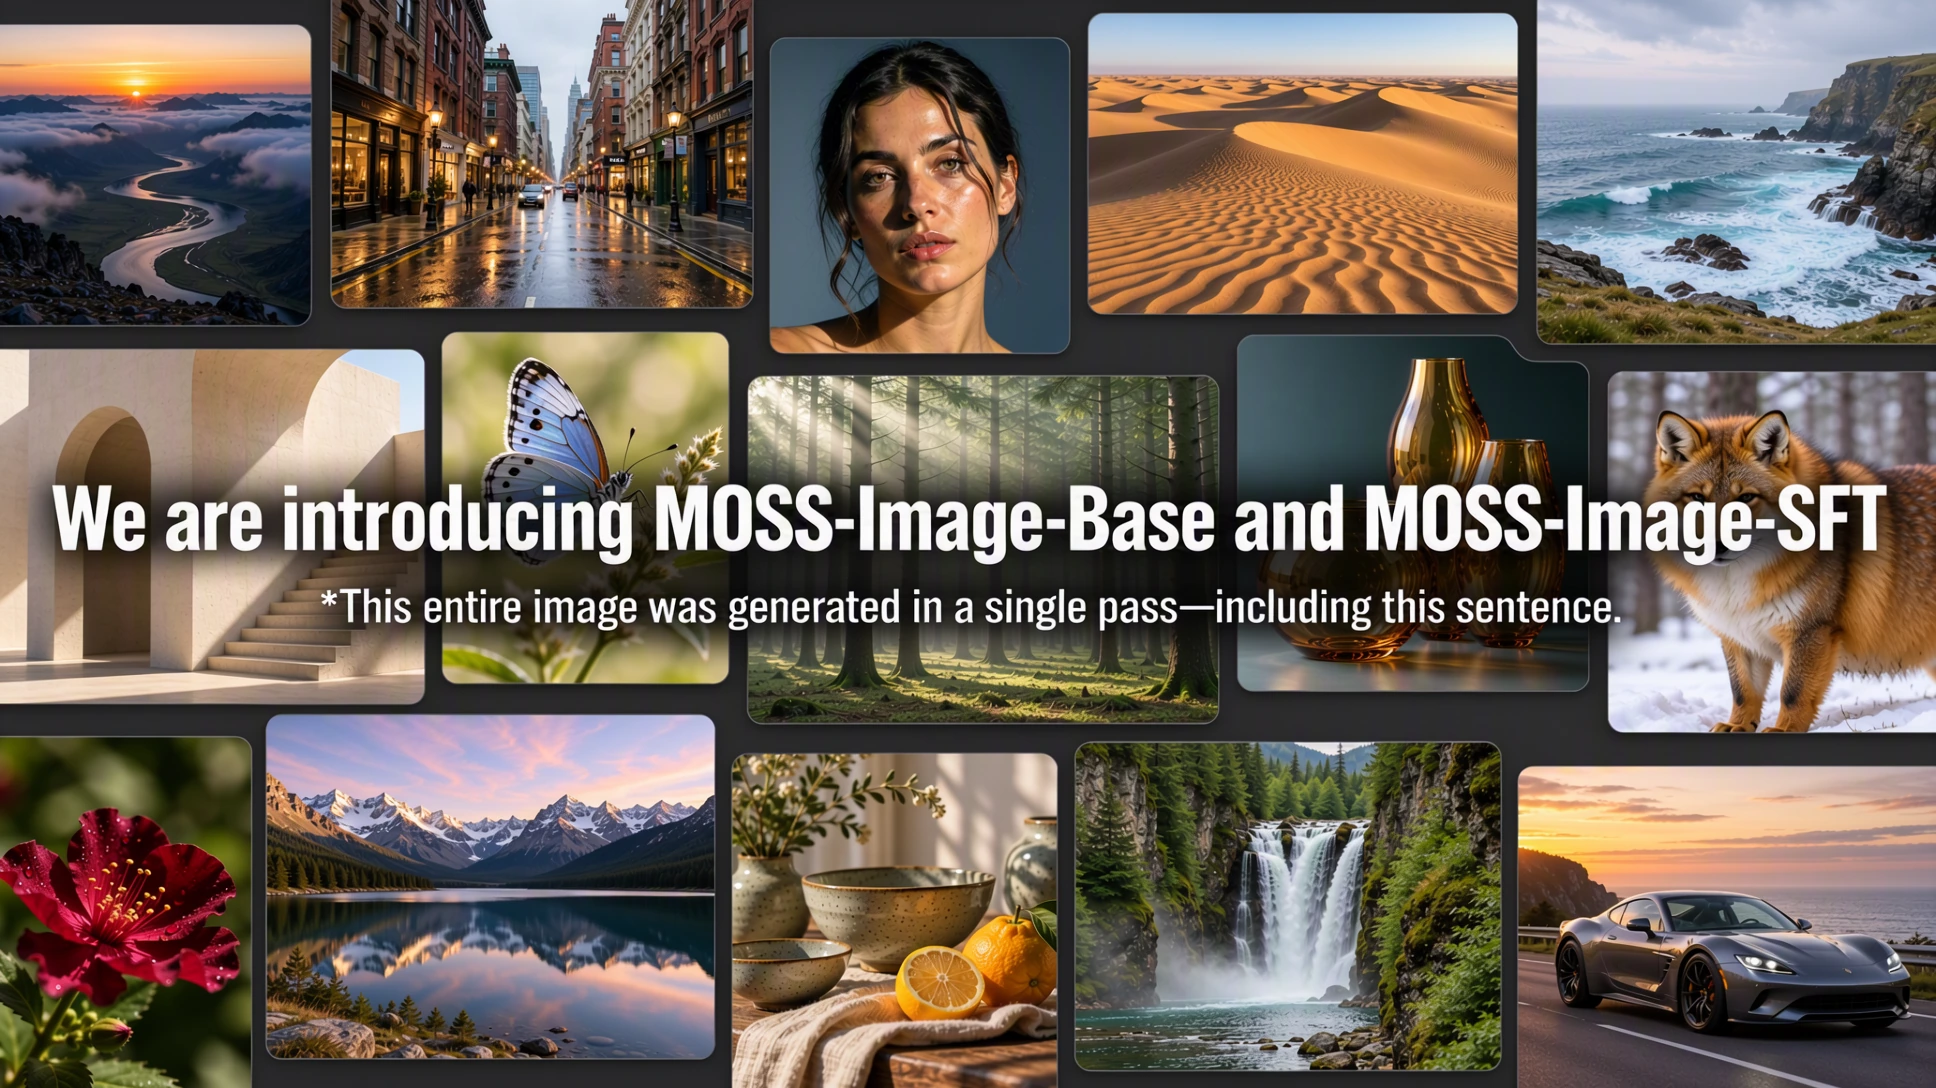
🎨 OpenMOSS opens MOSS-Image — an open text-to-image model with a JSON scene
On October 16, 2026, the code and weights were released under Apache-2.0: Base and SFT fine-tuned versions on a DiT backbone, 5B parameters. Composition is specified with a JSON prompt containing objects, text, and bounding boxes — the scene is edited structurally, not by guessing prompts. The model renders text inside images, including Chinese and handwritten text.
🌍 A ready-made open backbone for layout-to-image tasks — posters, infographics, UI mockups: the repository includes a LoRA guide, an official ComfyUI plugin, and Prompt Enhancer, with the VAE using the FLUX.2 small decoder.
👤 A demo is already available on Hugging Face Spaces; SFT weights can run locally on an NVIDIA GPU (Python 3.10+, PyTorch 2.9+, diffusers>=0.38) or via ComfyUI Manager. JSON simplifies edits, but there is no technical report or evals yet, and the data provenance has not been disclosed.
Source 1: https://github.com/OpenMOSS/MOSS-Image Source 2: https://huggingface.co/OpenMOSS-Team/MOSS-Image-SFT