🤖 LLM Prefill and Decode — in Different Quantizations
The IST-DASLab team in the paper “Disaggregated Quantization” fine-tunes a single LLM in two quantizations using the QADD method: an SFT token mask defines a phase-specific linear path for each token.
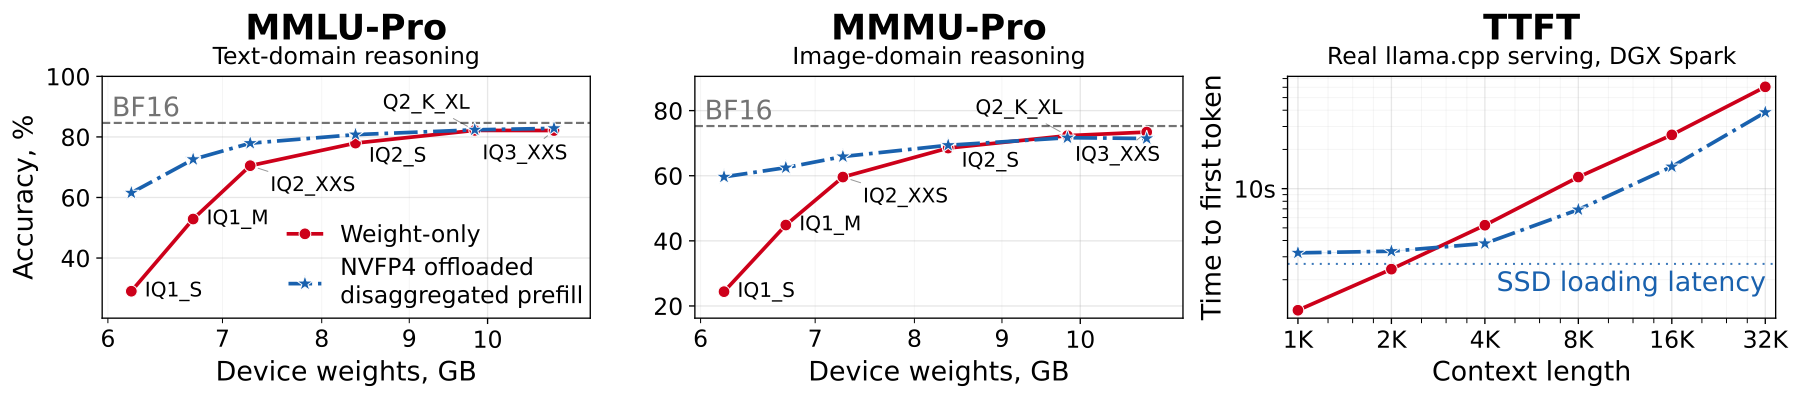
🌍 Inference stops being “one quantization for the entire run”: compute-bound prefill remains in compute-native NVFP4, memory-bound decode uses ultra-low-bit GGUF, and QADD recovers about half of the lost accuracy. The scheme is integrated into llama.cpp and validated in vLLM.
👤 On RTX 50-series or DGX Spark GB10, it is enough to download 1-2-bit GGUF Qwen3.8-27B and connect an NVFP4 prefiller from Hugging Face: MMLU-Pro increases from 29.04% to 61.54%, MMMU-Pro from 24.39% to 59.65%, GPU memory does not increase, and TTFT on 8K (DGX Spark) drops from 12.27 to 6.90 seconds. Short prompts remain slower due to loading from SSD.
Source 1: https://arxiv.org/abs/2609.26333 Source 2: https://github.com/IST-DASLab/disaggregated-quantization