🤖 Dream-RSI: Agent Accelerates Solution-Finding on Past Runs
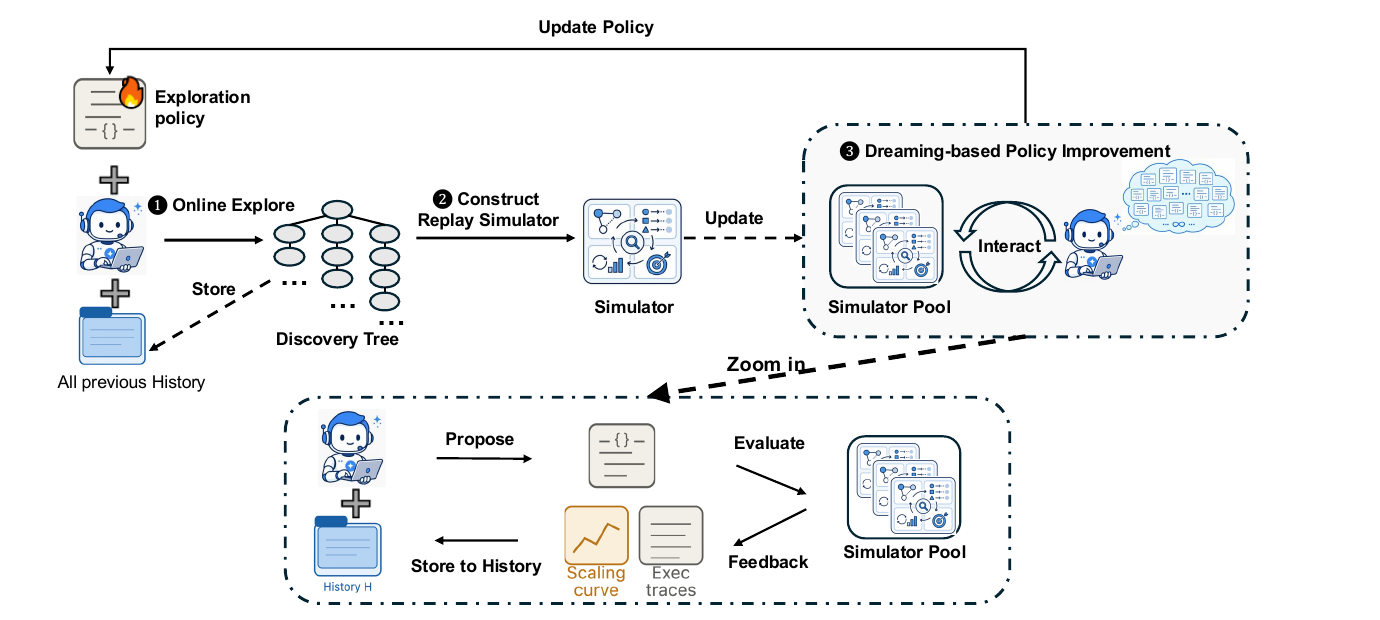
Google, Google DeepMind, and the Universities of Maryland and Virginia published the Dream-RSI preprint (arXiv:2609.14858): accumulated attempt trees act as an exact replay simulator, where thousands of alternative strategies are run without a single new agent call. A separate LLM agent rewrites the strategy code, the previous version participates in selection — the new one is guaranteed not to be worse.
🌍 Verifying a new self-improvement strategy usually requires re-running an expensive discovery cycle. Here, already-paid run logs become a free simulator: one online run pays for thousands of offline policy evaluations.
👤 For researchers in agent search, the method reduces the cost of meta-feedback: on Gemini 3.1 Pro, the Lasso solver accelerated from 3587 to 2931 ms with 317 calls instead of 550.
Source 1: https://dream-rsi.com/ Source 2: https://arxiv.org/abs/2609.14858