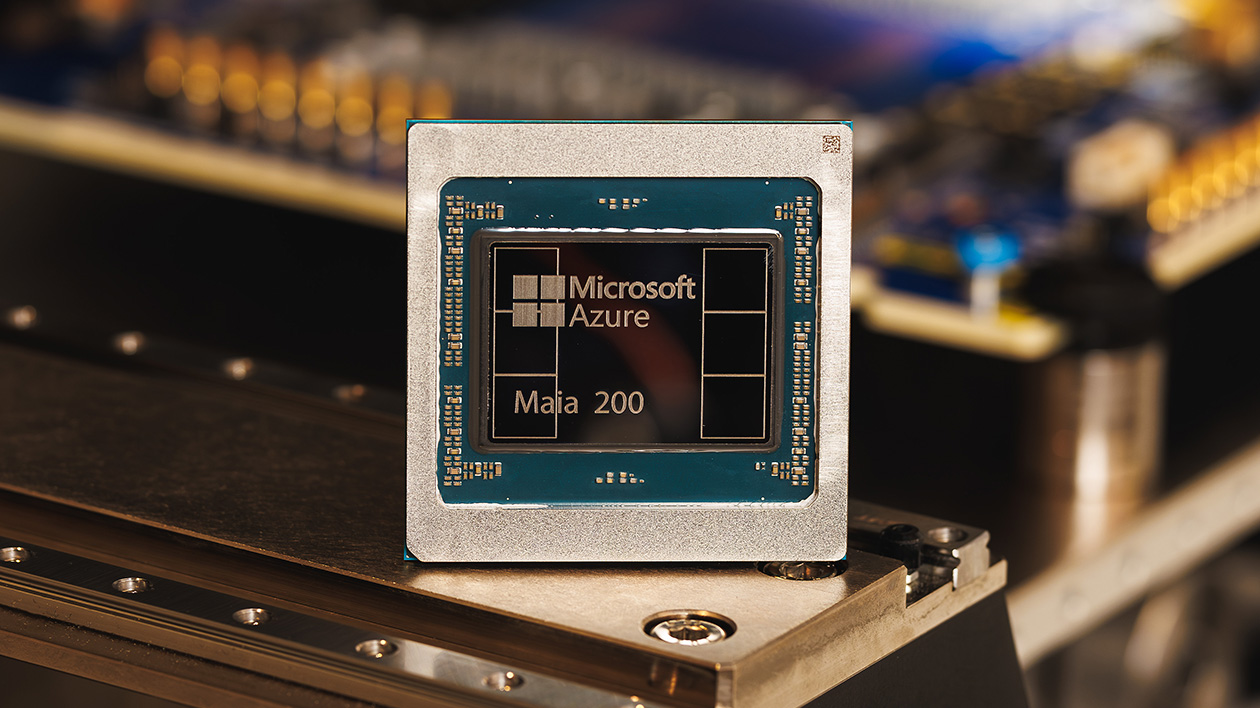
💻 Microsoft Reveals Maia 200 AI Accelerator Architecture
At Hot Chips 2026, the company showed its second-generation Maia for inference in Azure: TSMC 3nm, 140 billion transistors, 750W, 6 HBM3e stacks for 7 TB/s, and up to 10,000 TFLOPS in FP4. The core is SDLA: data flow is fixed at compile time, and memory access is local within tiles.
🌍 A third path between NVIDIA GPUs and ASICs like TPU: a data-movement-centric architecture and a unified Ethernet fabric instead of a separate scale-up interconnect. The reference design is 128 racks and 6,000 chips, with collectives via MCCL.
👤 The public picture of a hyperscaler's non-NVIDIA accelerator: GEMM operates near the theoretical limit, attention achieves an effective 1.65 PFLOPS, and BF16 AllReduce reaches about 1.3 TB/s. This is the hardware running Copilot and OpenAI models in Azure.
Source 1: https://www.servethehome.com/microsofts-maia-200-accelerator-at-hot-chips-2026/ Source 2: https://news.ycombinator.com/item?id=49442682