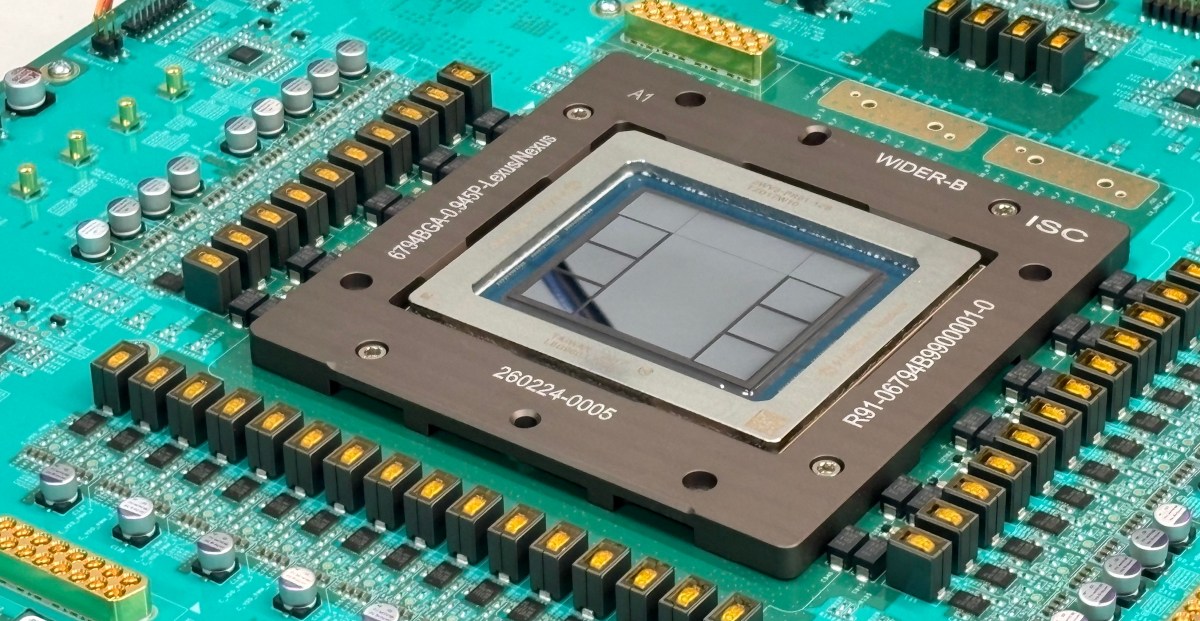
💻 OpenAI Shows First Results for Jalapeño Inference Chip
At Hot Chips on August 25, OpenAI announced figures for Jalapeño, its inference ASIC developed with Broadcom. According to SemiAnalysis's InferenceX, the chip delivers 1.5–1.9 times more AI work per watt and 1.7–3.6 times lower end-to-end latency than the best results on NVIDIA GB200/GB300.
🌍 The ASIC targets the most expensive part of the AI economy — inference costs. If the figures are confirmed, OpenAI's request costs will fall, and its negotiating position against NVIDIA will strengthen. Mass production — 2027.
👤 In the long run, this hardware will determine response latency in ChatGPT and the API: more responsive agents and voice modes. But the figures are currently manufacturer-claimed, and there are no mass shipments before 2027.
Source 1: https://openai.com/index/jalapeno-first-results/ Source 2: https://techcrunch.com/2026/08/25/openais-jalapeno-chip-is-built-for-fast-inference-at-scale-benchmarks-show/