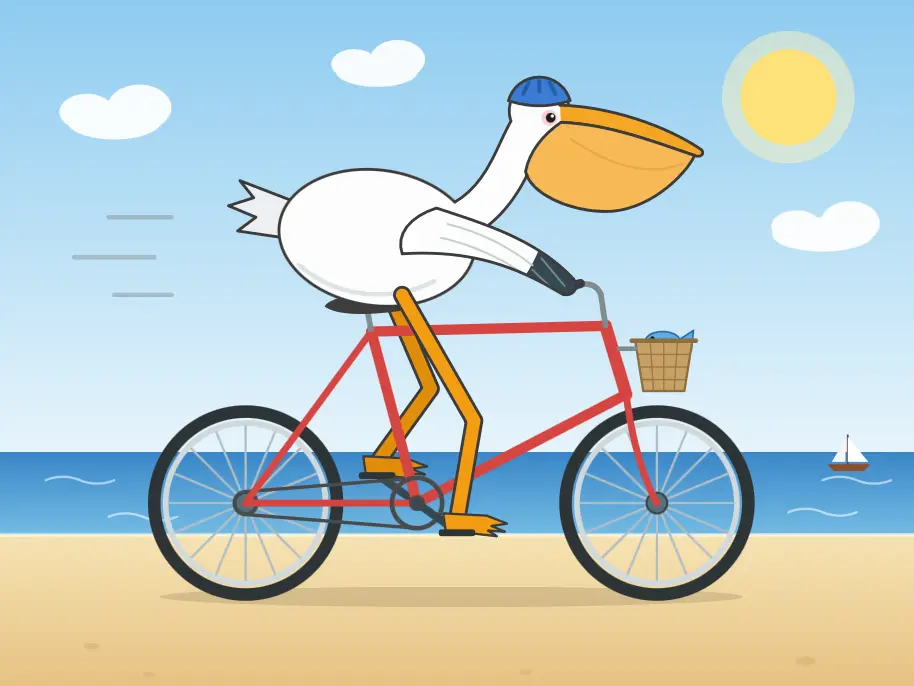
Simon Willison tested Anthropic's new Claude Fable 5.1 model on his signature 'pelican on a bicycle' test and ran it across all five reasoning effort levels: low, medium, high, xhigh, and max. The model's reasoning cannot be fully disabled, and raising the level makes generation disproportionately more expensive and slower: from cents and seconds on the lower steps to dollars and tens of minutes on the maximum. The author got the best result among all Anthropic models at the max level and, at the request of a Hacker News commenter, animated it with the same model. At the same time, Anthropic calls Fable 5.1 a new benchmark for coding: on the fresh Terminal-Bench-Science 0.1 benchmark, the model more than doubled the result of the previous version of the family.
What happened
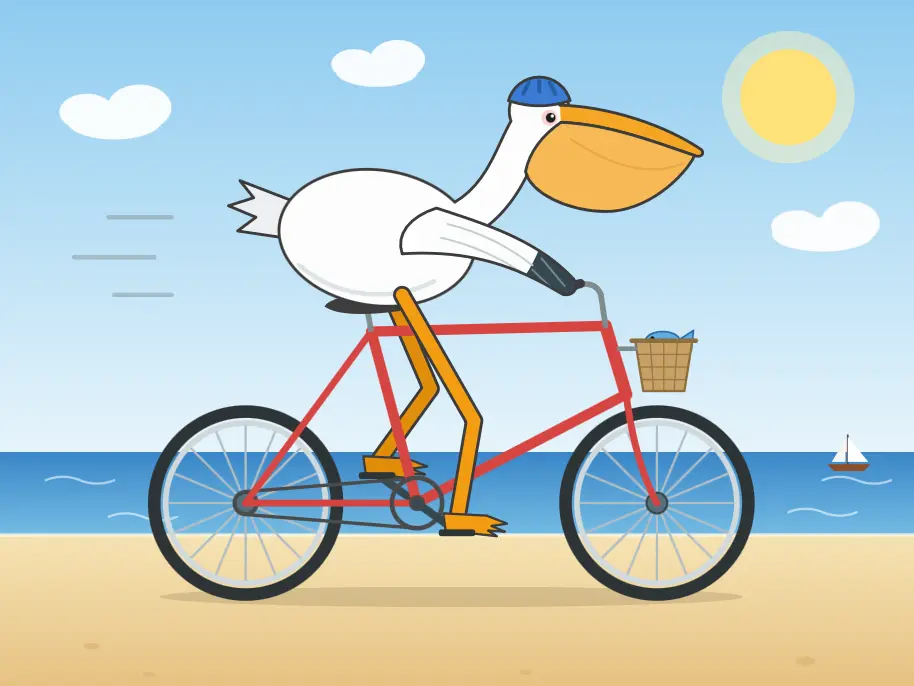
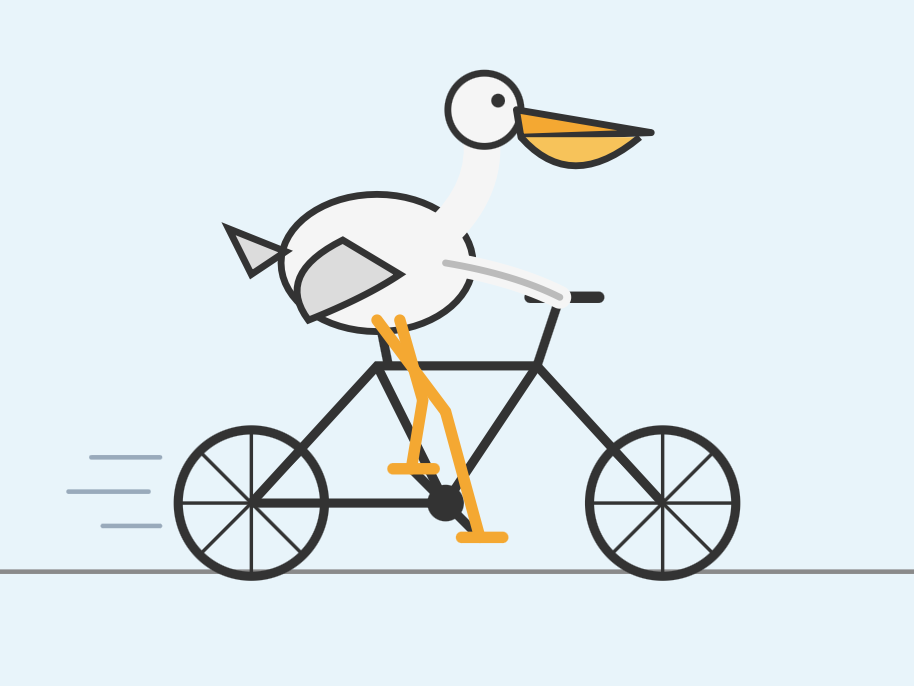
Willison sent the model the same prompt 'Generate an SVG of a pelican riding a bicycle' at the low, medium, high, xhigh, and max levels and published all five results along with transcripts. The level increase is non-linear: the xhigh step cost $1.83 and 7 minutes 51 seconds for 36,767 tokens, while max required 65,927 tokens. The author notes a mystery: on low and medium, there are no traces of reasoning in the transcripts at all. He recognized the max-level pelican as the best among all Anthropic models and, at the request of Hacker News commenter swalsh, animated it with the same model for $1.37 — 6,121 input and 26,201 output tokens; in the MP4-converted video, the wheels spin 'the wrong way' due to the conversion.
Context
Willison uses the 'pelican on a bicycle' test as a quick ad-hoc eval: from a single SVG image, you can see how carefully the model follows instructions and works with vector graphics. The second part of the context is the positioning of the model itself: Anthropic is promoting Fable 5.1 as a new benchmark for coding, and on the Terminal-Bench-Science 0.1 benchmark, announced on August 27, 2026, it scores 52.6% compared to 24.7% for the previous version of the family. For reference, GPT-5.6 Sol gives 22.4% on the same benchmark, and Opus 5 — 29.0%. The reasoning effort scale thus becomes a key characteristic of the model: it is this, and not just the 'raw' version of the model, that determines the final quality and behavior.
Why this matters for the industry
The reasoning effort level has become the main regulator of cost, latency, and quality in Claude: the same task costs from ~10 cents on low to $3.30 on max, and the gap between high and xhigh/max reaches approximately 14–50 times in token volume. There is no longer a no-reasoning mode, so a 'cheap and without thinking' configuration simply does not exist for the model. For companies, this is both a lever and a risk: margins are squeezed by effort routing — low and medium for interactive and mass scenarios, xhigh and max only for background heavy tasks — and the effort selector can already be moved to the interface as a 'fast and cheap ↔ slow and expensive' slider, given that the budget depends on the vendor's pricing policy. The jump on Terminal-Bench-Science 0.1 within a single family is a rare case where a loud benchmark is accompanied by a visual demonstration, and if independent repetitions confirm the numbers, intra-family jumps of this scale will shift the baselines in coding agents. Another industry lesson is the rapid aging of ad-hoc evals: a visual test that worked in 2025 stopped correlating with the overall strength of the model by July 2026, so comparisons increasingly make sense to conduct within a single family and between effort levels.
Why this matters for users
The material is fully reproducible: all versions of the pelicans with full reasoning transcripts are collected in the author's gist, and the experience can be repeated with a single command llm -m claude-fable-5.1 using his llm utility. The MP4 version of the animation is attached directly to the post, so the level of animation created with a single prompt can be evaluated with your own eyes. Readers planning to work with the model should estimate the budget in advance: interactive scenarios on low and medium fit into cents, while heavy background tasks on xhigh and max require dollars per run and noticeable waiting. Finally, the comparison of images by levels in the same gist is a visual guide for those deciding whether the overpayment for the higher steps is justified.
What is still unknown / limitations
The pelican is a single subjective assessment by one author on one prompt, and Willison himself admits that the test no longer correlates with the overall strength of the model, so the 'best pelican' does not prove the superiority of Fable 5.1 outside its family. The Terminal-Bench-Science 0.1 numbers have not yet been independently confirmed: the benchmark was announced on August 27, 2026, a few days before publication, the methodology is not disclosed in the source, and cross-family comparisons are vulnerable to the selection of favorable conditions. The transparency of the lower levels is also in question: on low and medium, there are no traces of reasoning in the transcripts, so it is impossible to check what exactly the model is doing. Finally, the price and time measurements were made by a third party on a single task — SVG generation — and the economics may differ for other types of loads.
Sources
- Claude Fable 5.1 made me a really nice animated pelican — Simon Willison's Weblog
- Hacker News discussion: Claude Fable 5.1 made me a nice animated pelican
- Gist: full set of Fable 5.1 pelicans with reasoning transcripts (simonw)
Author
Look at AI, editorial team