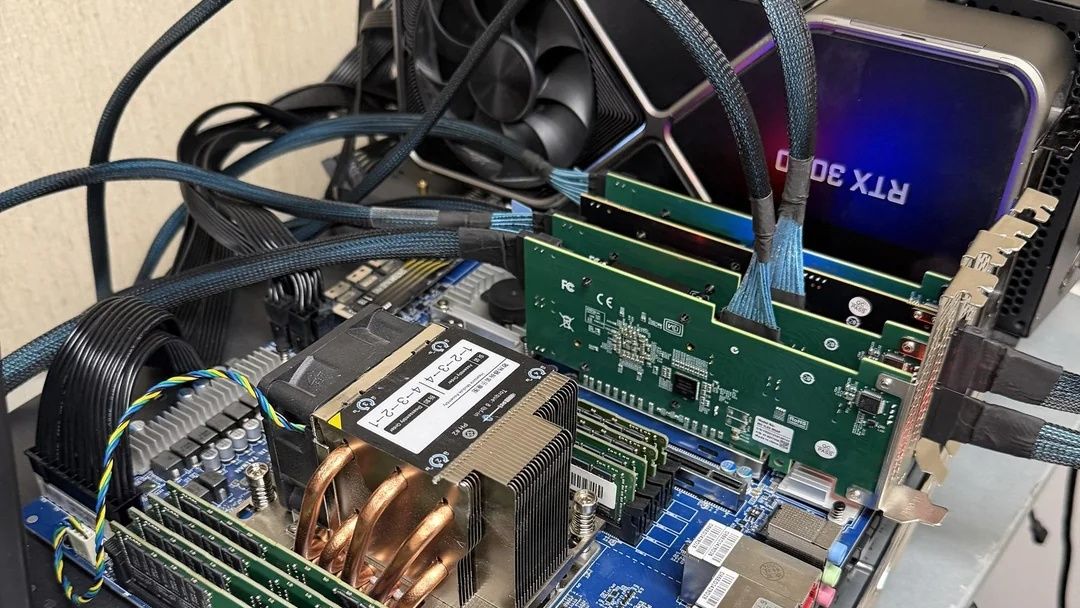
💻 Lawyer Runs DeepSeek V4.1 Flash on Eight Used Nvidia V100s
Nick Mermidjes from South Carolina added 1 TB of RAM and an RTX 3090 to his server, fixing crashes by replacing the power supply. 5,949 “hot” MoE experts out of 15,360 run in 4-bit NVFP4, while the rest run in 2-bit: context expanded to 524K, and token match with the reference NVFP4 version is 95.1%.
🌍 Mixed quantization—“hot” experts in NVFP4, “cold” ones in 2-bit—allows keeping a large MoE model on older Volta hardware, reducing the cost of local inference in places where data must not leave the office.
👤 The accuracy margin is small: 8 out of 513 responses still diverge, and legal texts are 9–23% slower—risky without human verification.
Source 1: https://www.tomshardware.com/tech-industry/artificial-intelligence/lawyer-upgrades-eight-v100-private-ai-server-to-run-80-percent-of-deepseek-v4-1-flash-at-4-bit-nvfp4-precision-adds-1tb-of-ram-an-nvidia-rtx-3090-and-fixes-crashes-caused-by-a-bad-psu