💻 Local Qwen3.x models generate up to twice as fast in ComfyUI v0.45.0
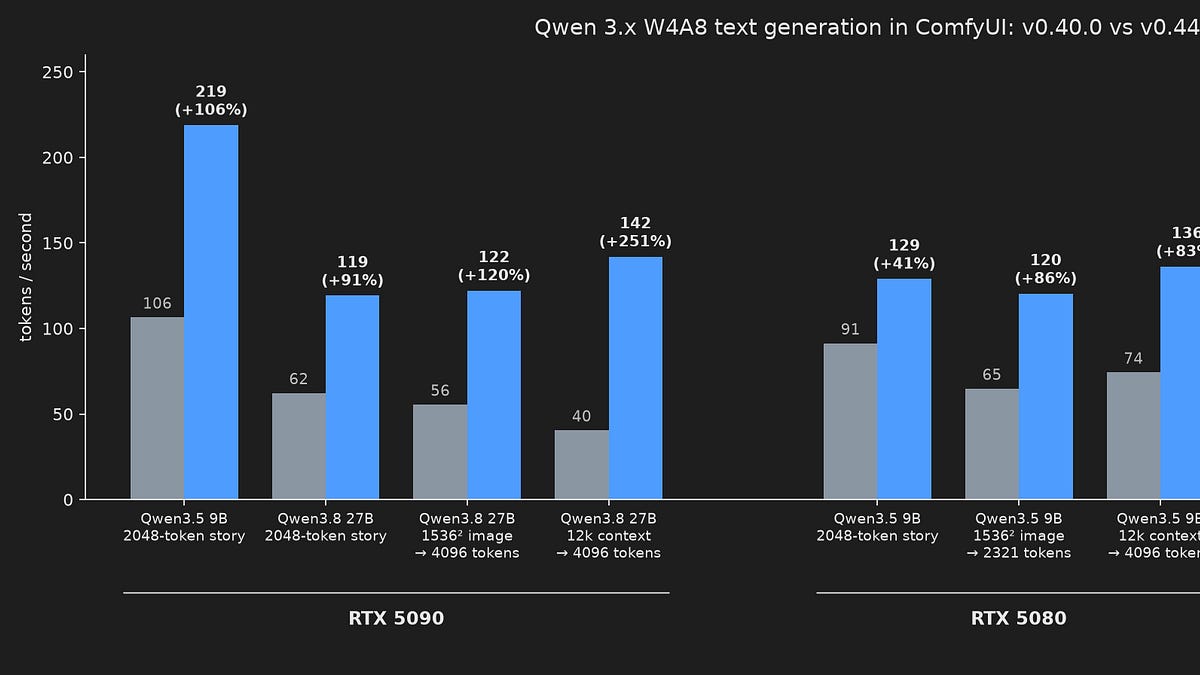
The team has rewritten the generation hot path: an optimized GEMV kernel, Tree MTP with tree-based speculation of up to 7 tokens, and INT8 attention via --use-ck-attention, which compresses the KV-cache and accelerates pre-fill. On an RTX 5090, Qwen3.5 9B now achieves 219 tokens/s instead of 106, and Qwen3.8 27B reaches 122 instead of 55.
🌍 The bottleneck for local inference is not compute, but VRAM bandwidth: each token requires a full read of the model weights. Optimizing this specific layer doubles the speed on consumer GPUs and reduces the time and cost of local text generation.
👤 Update to v0.45.0 and enable mtp=auto in the Text Generate node — speed will increase by up to 2x, with no change in quality according to the team. It works on NVIDIA and AMD, Windows and Linux, with no need to recompile anything.
Source 1: https://blog.comfy.org/p/doubling-llm-token-rates-in-comfyui