💻 Together Compiler: Coding Agents Continuously Accelerate AI Inference
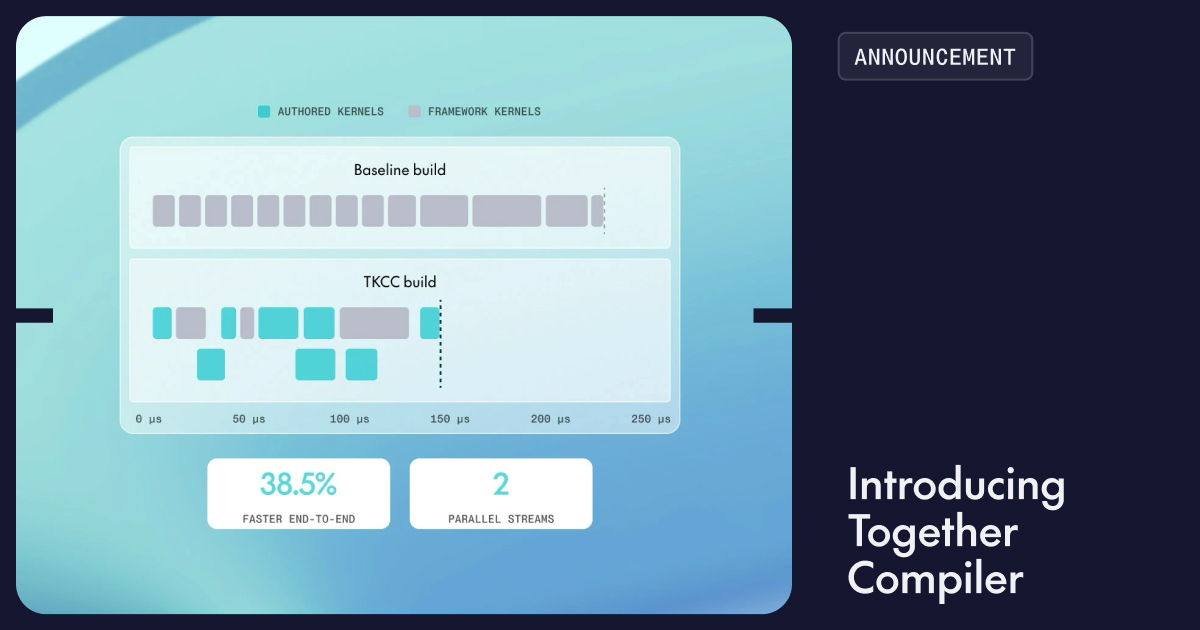
Together AI has introduced Together Compiler: agents rewrite model forward passes for current traffic and hardware, while the engine validates candidates without restarts, reducing startup time from 467 to 9 seconds. Within 24 hours, it achieved up to 2.6x TPS on Kimi K3, GLM 5.3, MiniMax M3.1-Flash, and DeepSeek v4.1-Flash — and SOTA in SemiAnalysis InferenceX: 1111 TPS on B200, 1205 on GB300.
🌍 From manual tuning to an automated loop: TKCC automatically adapts to traffic drift and GPU changes, reducing the cost and latency of LLM services.
👤 For LLM operators — a path to lower latency and cost: agents select parallelism strategies; "naive" approaches yielded 6.2x compared to 4.9x for expert-tuned setups — but this is a vendor measurement.
Source 1: https://www.together.ai/blog/together-compiler-continual-compilation-for-ai-inference Source 2: https://www.marktechpost.com/2026/11/05/together-ai-together-compiler-continual-compilation-ai-inference/