🤖 Agent sessions turn into ready-made evals
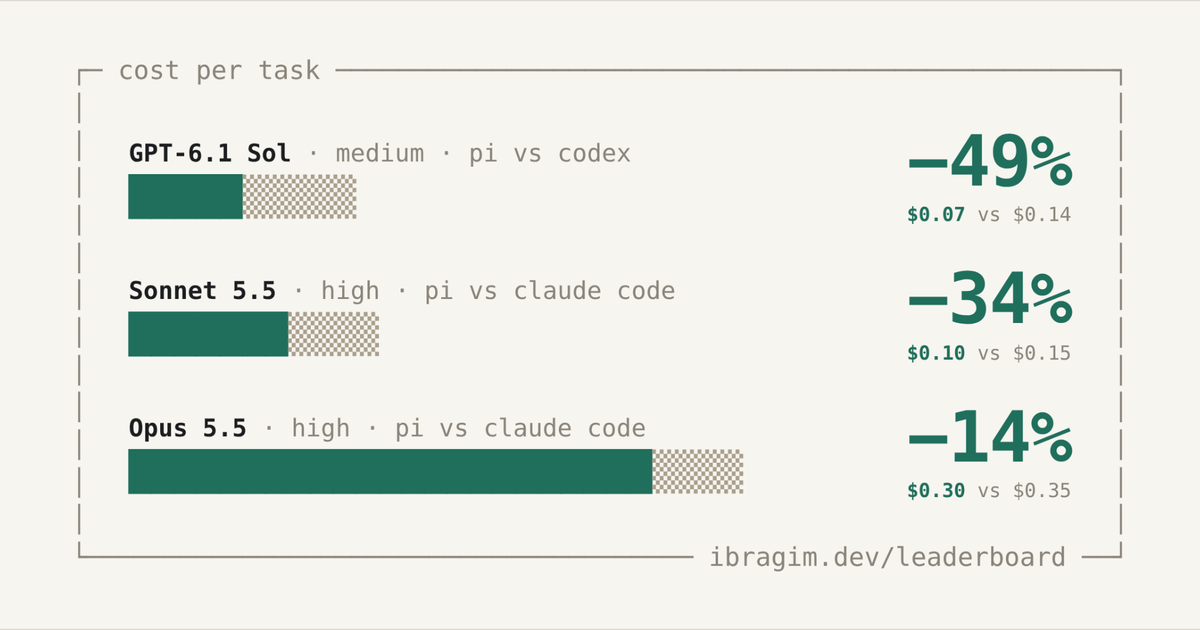
Nebius developer Ibragim Badertdinov (SWE-rebench) released the evals-from-sessions skill: your session history in Claude Code, Codex, and Pi turns into private eval tasks with automatic checking. From ~1,270 sessions, he built 10 tasks: the Pi agent on GPT-6.1 Sol (medium) solved all of them for an average of $0.070, while Codex cost $0.138.
🌍 Teams working with coding agents will be able to compare models, skills, and MCP servers by cost and time on their real tasks, rather than on public benchmarks.
👤 The skill (MIT) is installed via npx skills add ibragim-bad/evals-from-sessions: build your own tasks and check whether another agent can solve them cheaper — the author saved half on tokens this way. Caveat: only 10 tasks with human review came out of 1,270 sessions, and the conclusions are valid for his tasks.
Source 1: https://teletype.in/@ibragim_bad/fm5jSJvYb_5 Source 2: https://github.com/ibragim-bad/evals-from-sessions