💻 Same LLM Weights — Different Answers on MacBook and Jetson
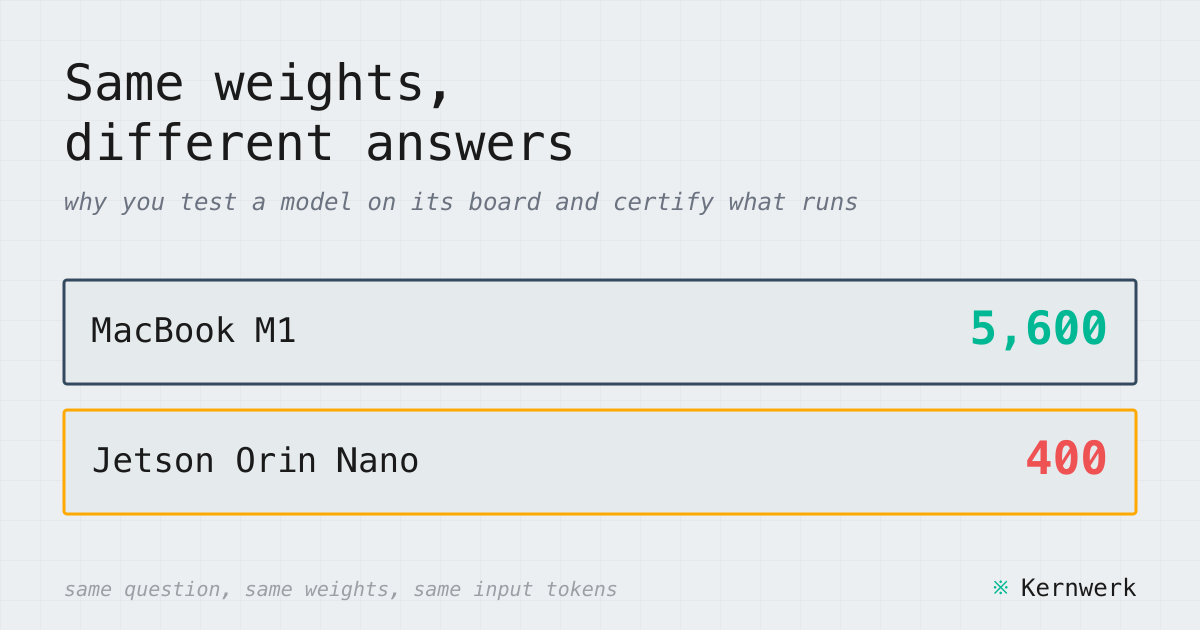
Kernwerk ran the same Qwen2.5-1.5B-Instruct weights file on both systems: the aggregate difference is up to 0.5 percentage points, but 18 of 250 GSM8K answers differ. In int8, 53.2% of answers change and the score drops by 11.2 points (partly due to TensorRT-LLM quantization). Because of non-associative FP summation, when logits are nearly equal, the answer "flips."
🌍 A benchmark from a different machine does not guarantee answers on the target board: you need engine tests on the device and item-by-item verification. A NeurIPS 2026 paper (FloatDoor) shows an attack vector: a LoRA adapter makes Qwen3-8B write vulnerable code in 49% of programs on A100 versus 16% on H200.
👤 The same weights on different hardware produce different answers — especially in int8. Verify answers on the target device, not by scores from someone else's machine.
Source 1: https://kernwerk.org/blog/same-model-different-board/ Source 2: https://news.ycombinator.com/item?id=50109547