🤖 ByteDance Releases DuoMatching — Video Model Distillation with an Image Teacher
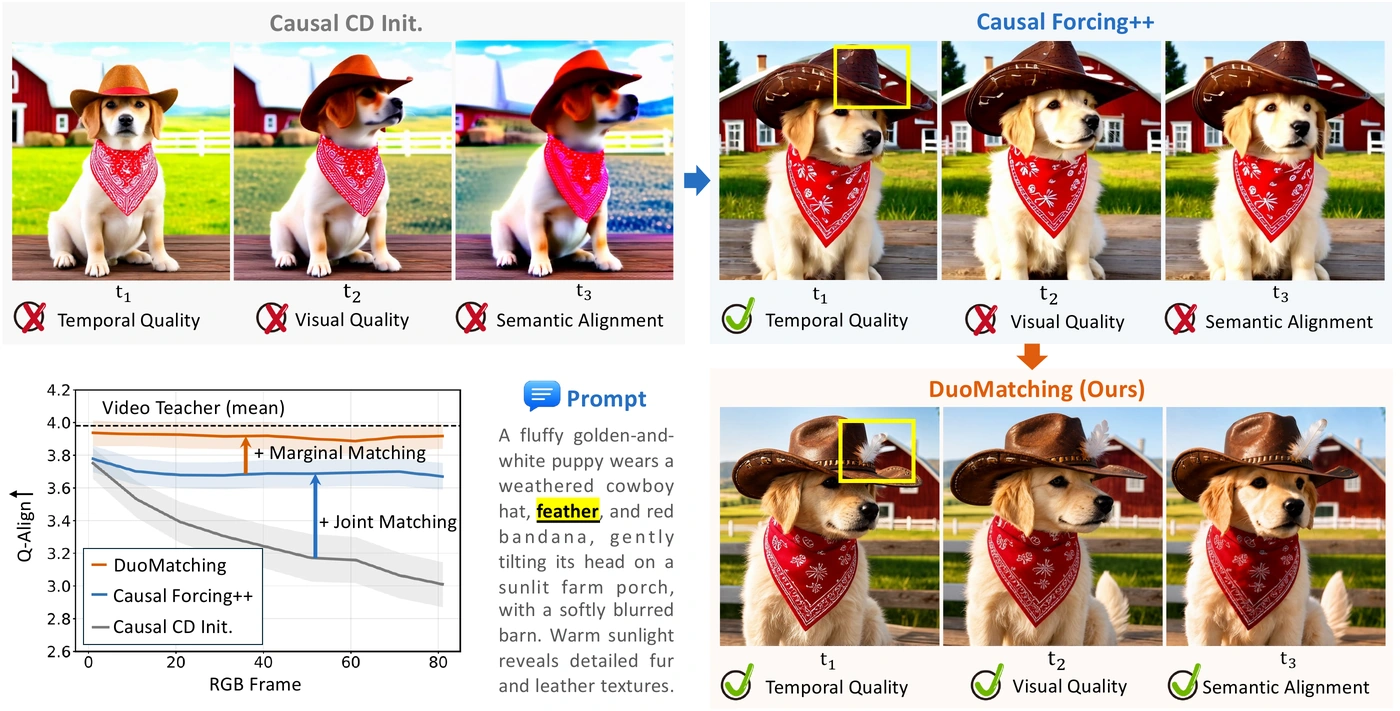
ByteDance, MMLab CUHK, and HKUST published the DuoMatching preprint (arXiv 2610.03543, October 2, 2026). The method distills Wan2.1-T2V-14B to two steps and, through per-frame matching and LatentBridge, inherits the visual and semantic priors of Qwen-Image. In the authors' human evaluation, it won over 80% of preferences against Causal Forcing++, One-Forcing, Reward Forcing, and CausVid.
🌍 Distilling to two steps brings streaming video generation closer to real-time, while transferring priors from images addresses the weakness of joint-DMD — the loss of quality and semantics in autoregressive rollouts.
👤 The code is open (Apache-2.0), and the 2-step checkpoint is on HuggingFace: generate on your own GPU via inference.py or view around 40 paired comparisons on the project page.
Source 1: https://arxiv.org/abs/2610.03543 Source 2: https://johnzhan2023.github.io/DuoMatching/