💻 Open-VC Attention Code Released: FP8 Attention for Blackwell Is Twice as Fast
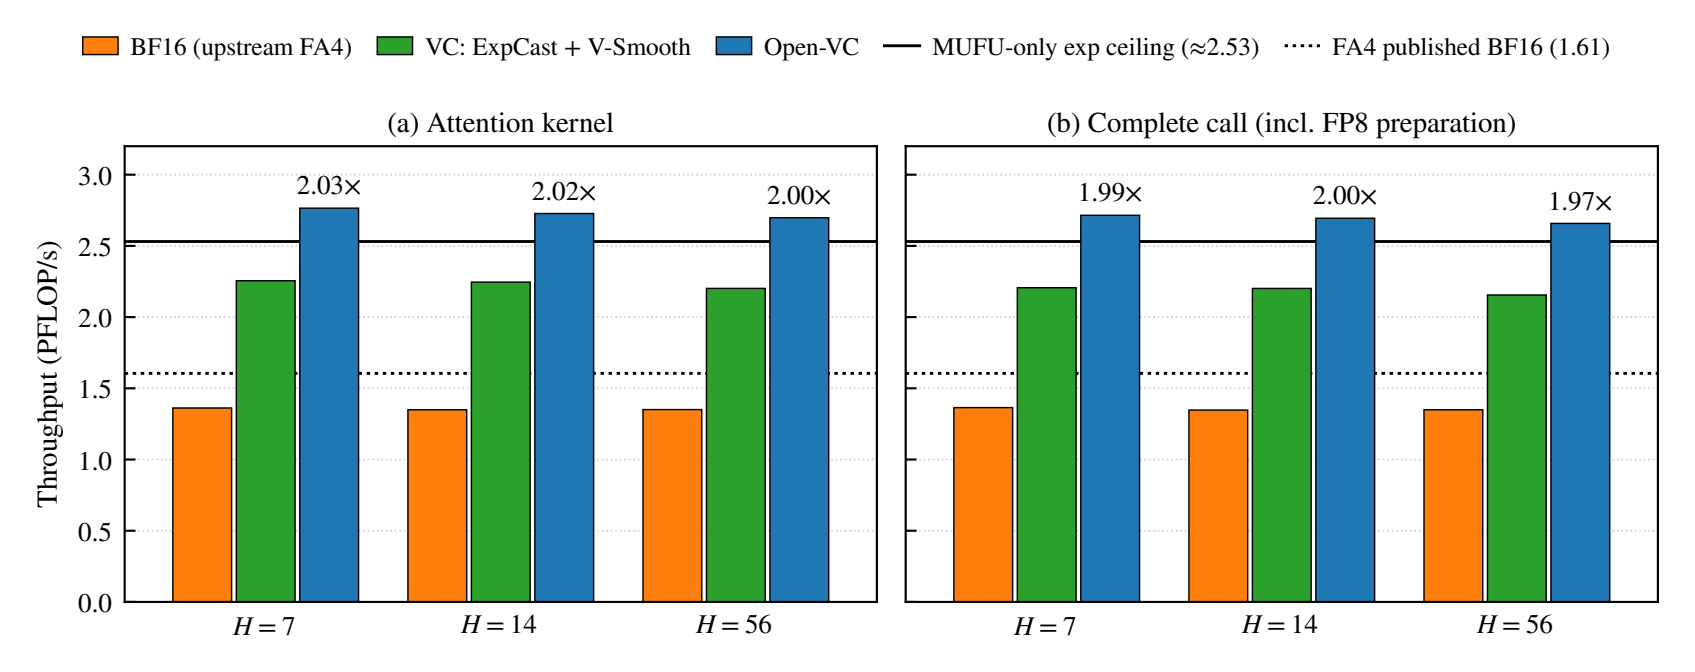
MachGen has released a library under the BSD-3-Clause license: FP8 kernels on CuTe DSL based on FlashAttention-4 implement ExpCast from the VC-Attention paper (arXiv 2609.15810). On the MiniMax-H3 video model, this is 2.00–2.03× over BF16 FlashAttention-4 with an L2 error of 2.98–3.19%.
🌍 Attention is the most expensive part of video generation, and on Blackwell, kernels are bottlenecked by the MUFU special function unit (~2.53 PFLOP/s, half of B200's FP8 peak): softmax exponentials go through it. ExpCast computes FP8 probabilities in a single FMA without exponentials — hence the real ~2×.
👤 On B200/B300 with long video denoising, the kernel is installed via pip (Linux, Python 3.10+, CUDA 13 PyTorch), called with open_vc_attn.attention(q, k, v) with BF16 inputs. Error is adjusted by the V residual repair budget (budget=0.005); not validated on other models.
Source 1: https://www.machgen.ai/blog/open-vc-attn
Source 2: https://github.com/MachGen/open-vc-attention