🤖 Pretraining LLMs Without Human Data: Proof-of-Concept
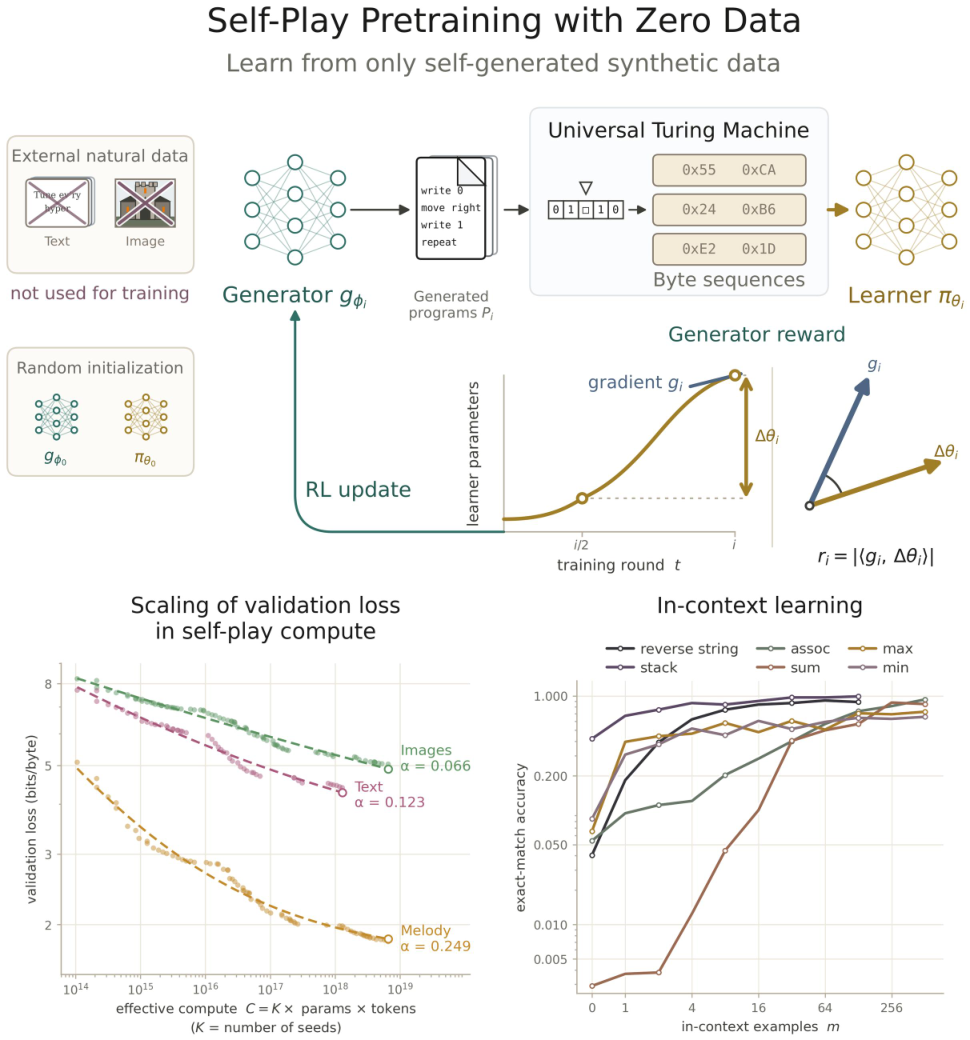
On September 24, a preprint titled “Self-Play Pretraining with Zero Data” (2609.30063) was published on arXiv: the generator and learner start from random initialization — the generator proposes programs, they are executed on a Turing machine and generate bytes, the learner predicts them via cross-entropy, and the generator receives an RL reward for data at the boundary of the learner's capabilities.
🌍 The volume of useful training data here becomes a function of compute: zero-shot loss predictably drops on natural datasets with the growth of self-play computations, but this is still only a small proof-of-concept.
👤 A model that has never been trained on natural data found recognizable mathematical sequences and acquired in-context learning — unlike Absolute Zero (2505.03335), where self-generated tasks only fine-tuned reasoning.
Source 1: https://arxiv.org/abs/2609.30063 Source 2: https://arxiv.org/pdf/2609.30063