🤖 AI Agent Memory: Store Beats Files by +28.7 Percentage Points
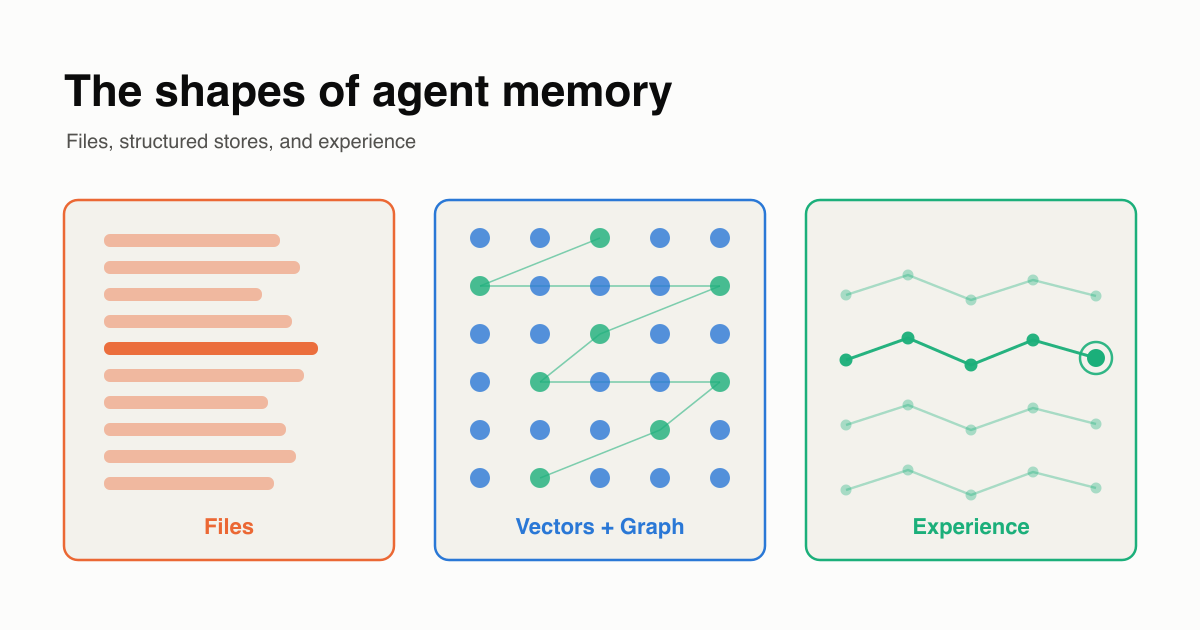
Engineer Pin Lin (pinglin.tw) ran three forms of agent memory through LongMemEval and LoCoMo on a single model: files curated by the model itself (Claude Code, Cursor), a structured store (mem0, Letta, Zep), and RL experience in the weights (MemHarness).
🌍 In the memory vendor industry, published metrics are incomparable: Zep's LoCoMo result appeared as 84, 58.44, and 75.14, while mem0 appeared as 67 and 92.5 due to different methods. Here, instead of a single number, there are line-by-line verdicts with a verifier: the verify_all.py script recalculates every number and fails on a mismatch.
👤 For your own agent, file-based memory (MEMORY.md plus grep) is cheap and honestly answers 'I don't know,' but it loses to the store on long histories: on LongMemEval-S, the store has +28.7 percentage points of accuracy and 19.3k tokens per question versus 286.5k.
Source 1: https://pinglin.tw/blog/the-shapes-of-agent-memory/ Source 2: https://github.com/a40-labs/memory