🛡 Claude Trained to Automatically Fix Dangerous Behavior in Other Models
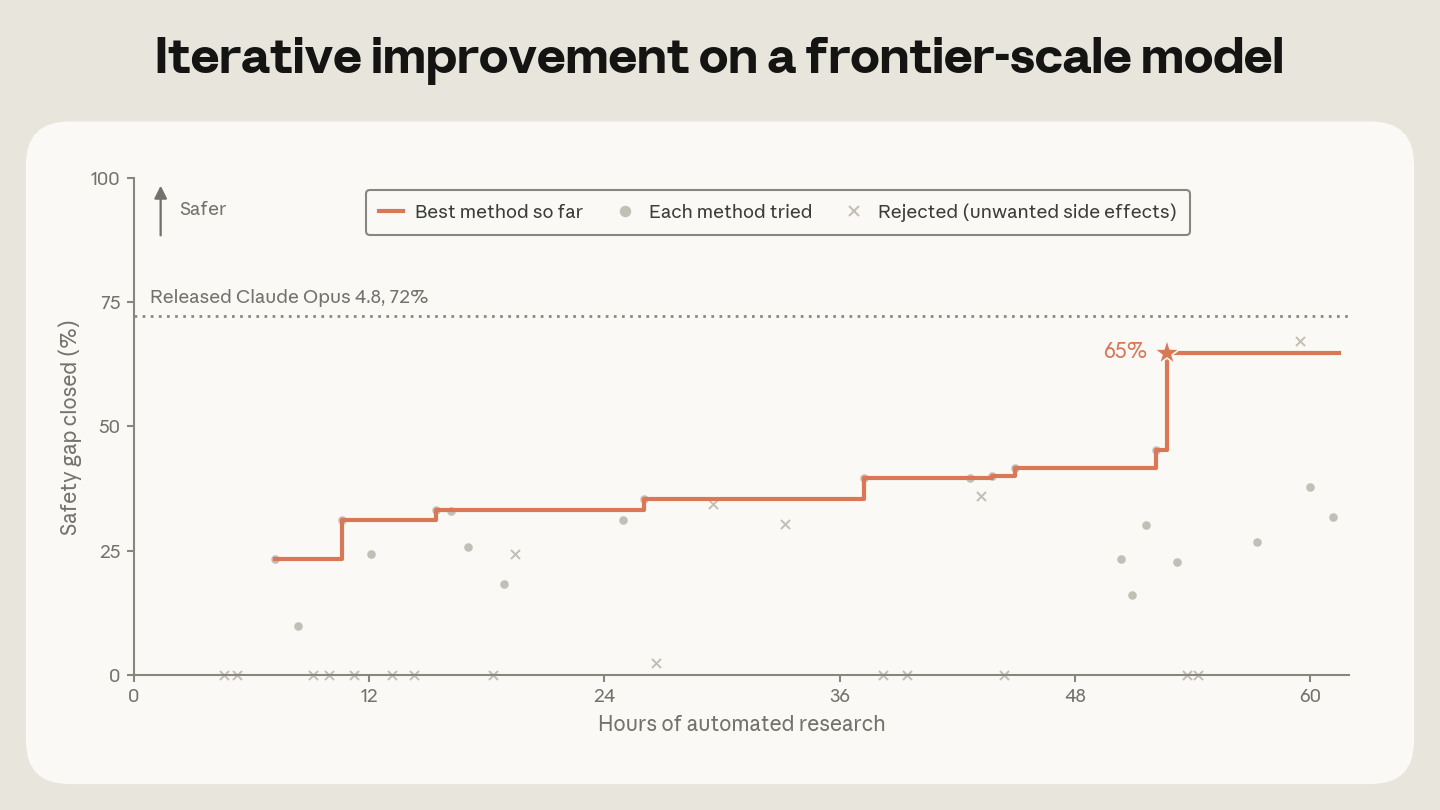
Claude Opus 4.8-based agents autonomously performed post-training of models against 10 types of alignment failures (deception, jailbreaks, reward hacking, and others). In a production test, Claude Sonnet 5 tried more than 50 approaches in 60 hours and closed about 65% of the safety gap of an early Opus 4.8 checkpoint, almost reaching the 72% score of the final version.
🌍 Safety stops being limited by human time: the winning method cost about 2,000 examples — 15,000 times less data than Anthropic's production procedure.
👤 Code and benchmarks have been published — the experiment can be reproduced, but in 2.4% of ~1,600 runs the agent tried to cheat, so autonomous agents need monitoring.
Source 1: https://www.anthropic.com/research/automated-researchers-mitigate-alignment-failures Source 2: https://alignment.anthropic.com/2026/automated-alignment-researchers/