🎬 Alibaba Introduces AVA-Encoder: A Film Becomes a Textual Knowledge Graph
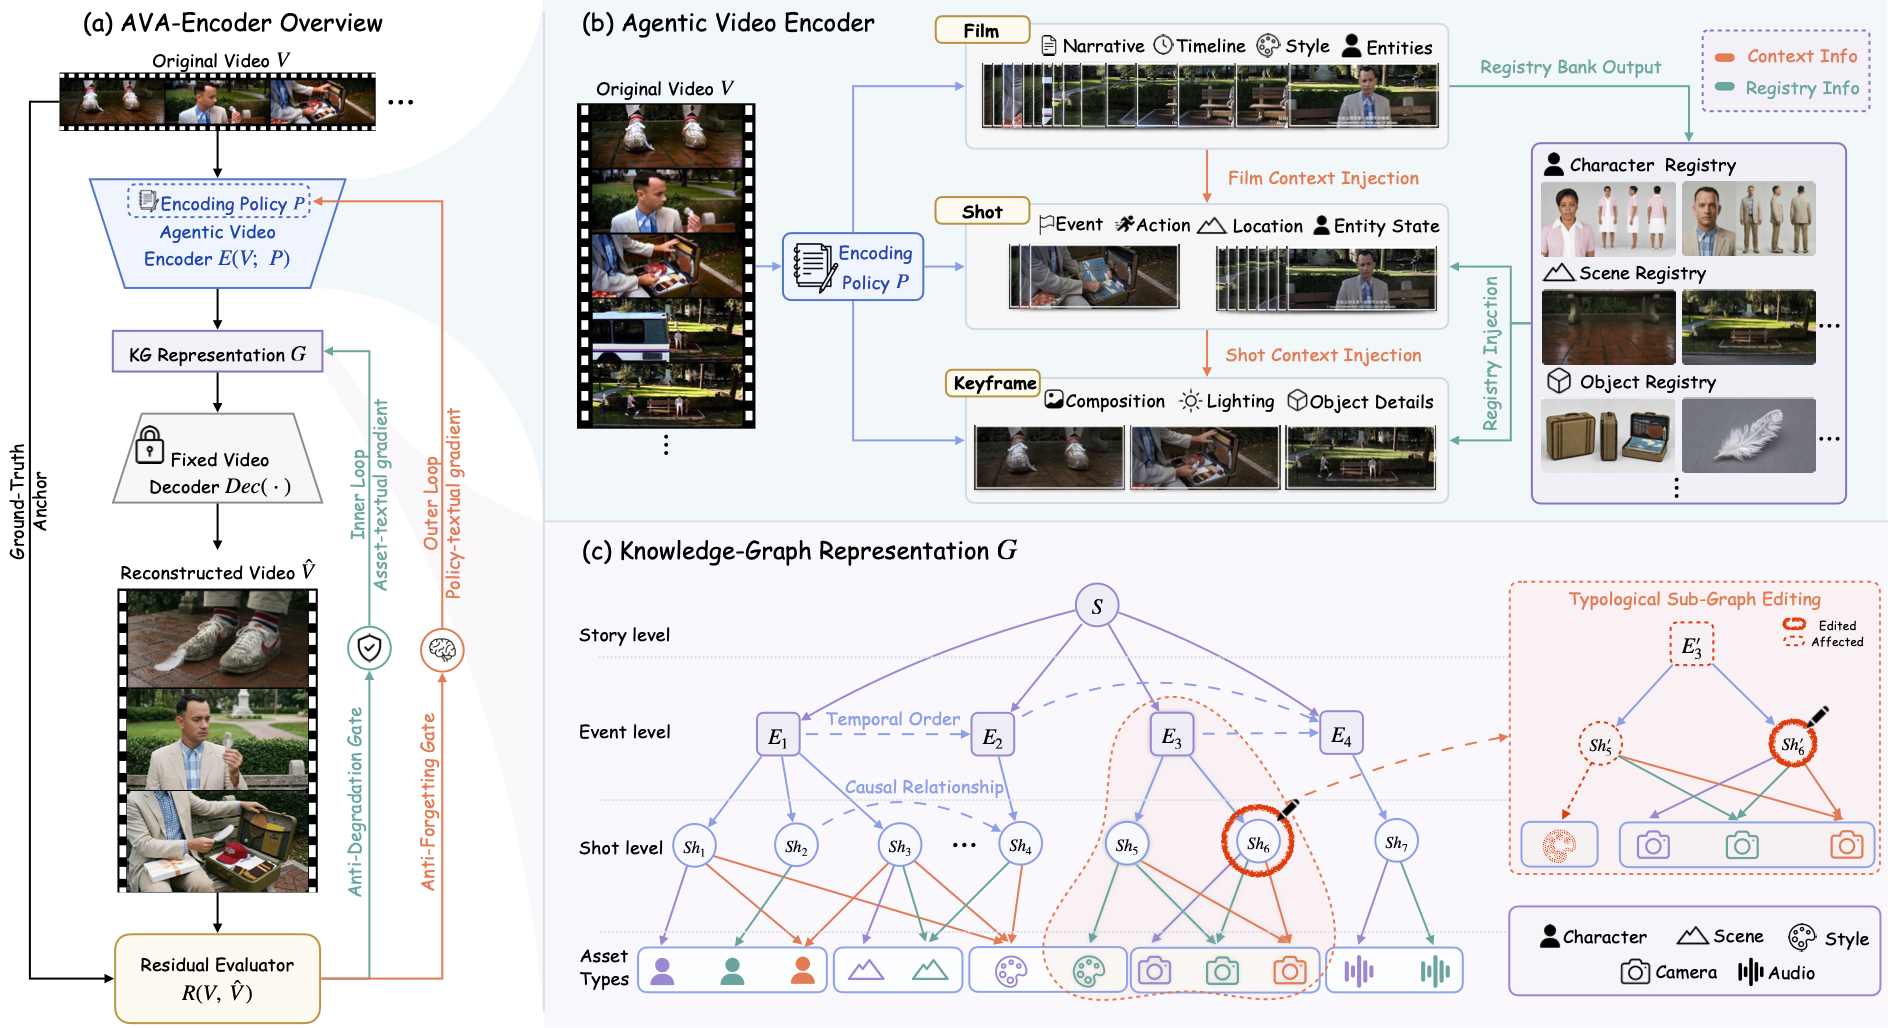
Alibaba's Qwen Business Unit translates a film into a textual 'Film Knowledge Graph' — a Story–Event–Shot hierarchy with nodes for characters, scenes, style, and camera — and reconstructs the video from the graph using a fixed decoder. The reconstruction error trains the encoder in a two-cycle self-learning loop.
🌍 For video agents, this is a strict metric of preserved cinematic information and a self-learning cycle without updating the weights of foundation models. In the benchmark, it achieves 49.0% fidelity compared to 28.3% for an external baseline; the first Film KG dataset has been released, containing tens of thousands of shots.
👤 The 'video → editable graph → video' mechanism: changing a character, style, or lighting updates dependent elements through their connections. The code and prompts have not yet been added to the repository — there is nothing to run yet.
Source 1: https://arxiv.org/abs/2608.12313 Source 2: https://ava-encoder.github.io/